

why use many token when few do trick
Your AI coding agent bills by the word and writes like it knows that. Caveman make it stop.


🏆 #1 on GitHub Trending · July 2026 · 🥇 #1 Repository of the Day on Trendshift · April 2026
#1 on Hacker News · #8 Product of the Day
📄 Cited in CAVEWOMAN, an Adobe Research paper that measured caveman-style output cutting cost 1.4 to 2.4×, up to 3× · 🧪 Tested by JetBrains on 86 real coding tasks: "costs you nothing measurable in quality"

⚡ One command, no account, no API key. npx skills add JuliusBrussee/caveman -g → Quick Start
See it · Quick Start · The Numbers · How it compares · In the Wild · The Skill · The Proxy · Wrap · Your own app · When to Skip · Docs
🪨 See it
| 🗣️ Normal agent · 69 tokens |  Caveman agent · 19 tokens |
|---|---|
|
|
Same diagnosis. Same fix. Same useMemo. The only thing that died was the throat-clearing.
Code, commands, file paths, and exact error messages never get cavemanned. Only the prose around them does. Security warnings and "are you sure?" confirmations come back in full sentences on their own, then caveman resumes.
Caveman no make brain smaller. Caveman make mouth smaller.
Half the fun is that your agent talks like it just discovered fire. The other half is that it is still right.
🌍 Why this exists
A token is what AI billing counts, roughly three quarters of a word. Your agent pays for every token it writes and every token it reads. Most agents write like a cover letter and read like a firehose.
Caveman attacks both ends, in the agent you run and in the one you build:
- The skill shrinks what the agent says. One rule file. Free forever. Works in 30+ agents.
- The proxy shrinks what the agent reads: logs, test output, JSON, diffs, search results. Runs on your machine. Every squeezed byte gets a backup, so the agent can always pull the original back.
- The middleware does the same inside your own code: one wrapper around the LangChain, Vercel AI SDK, OpenAI, or Anthropic call you already make. Tool results get shrunk before the model sees them, the original stays in your history, and the model can fetch it back.
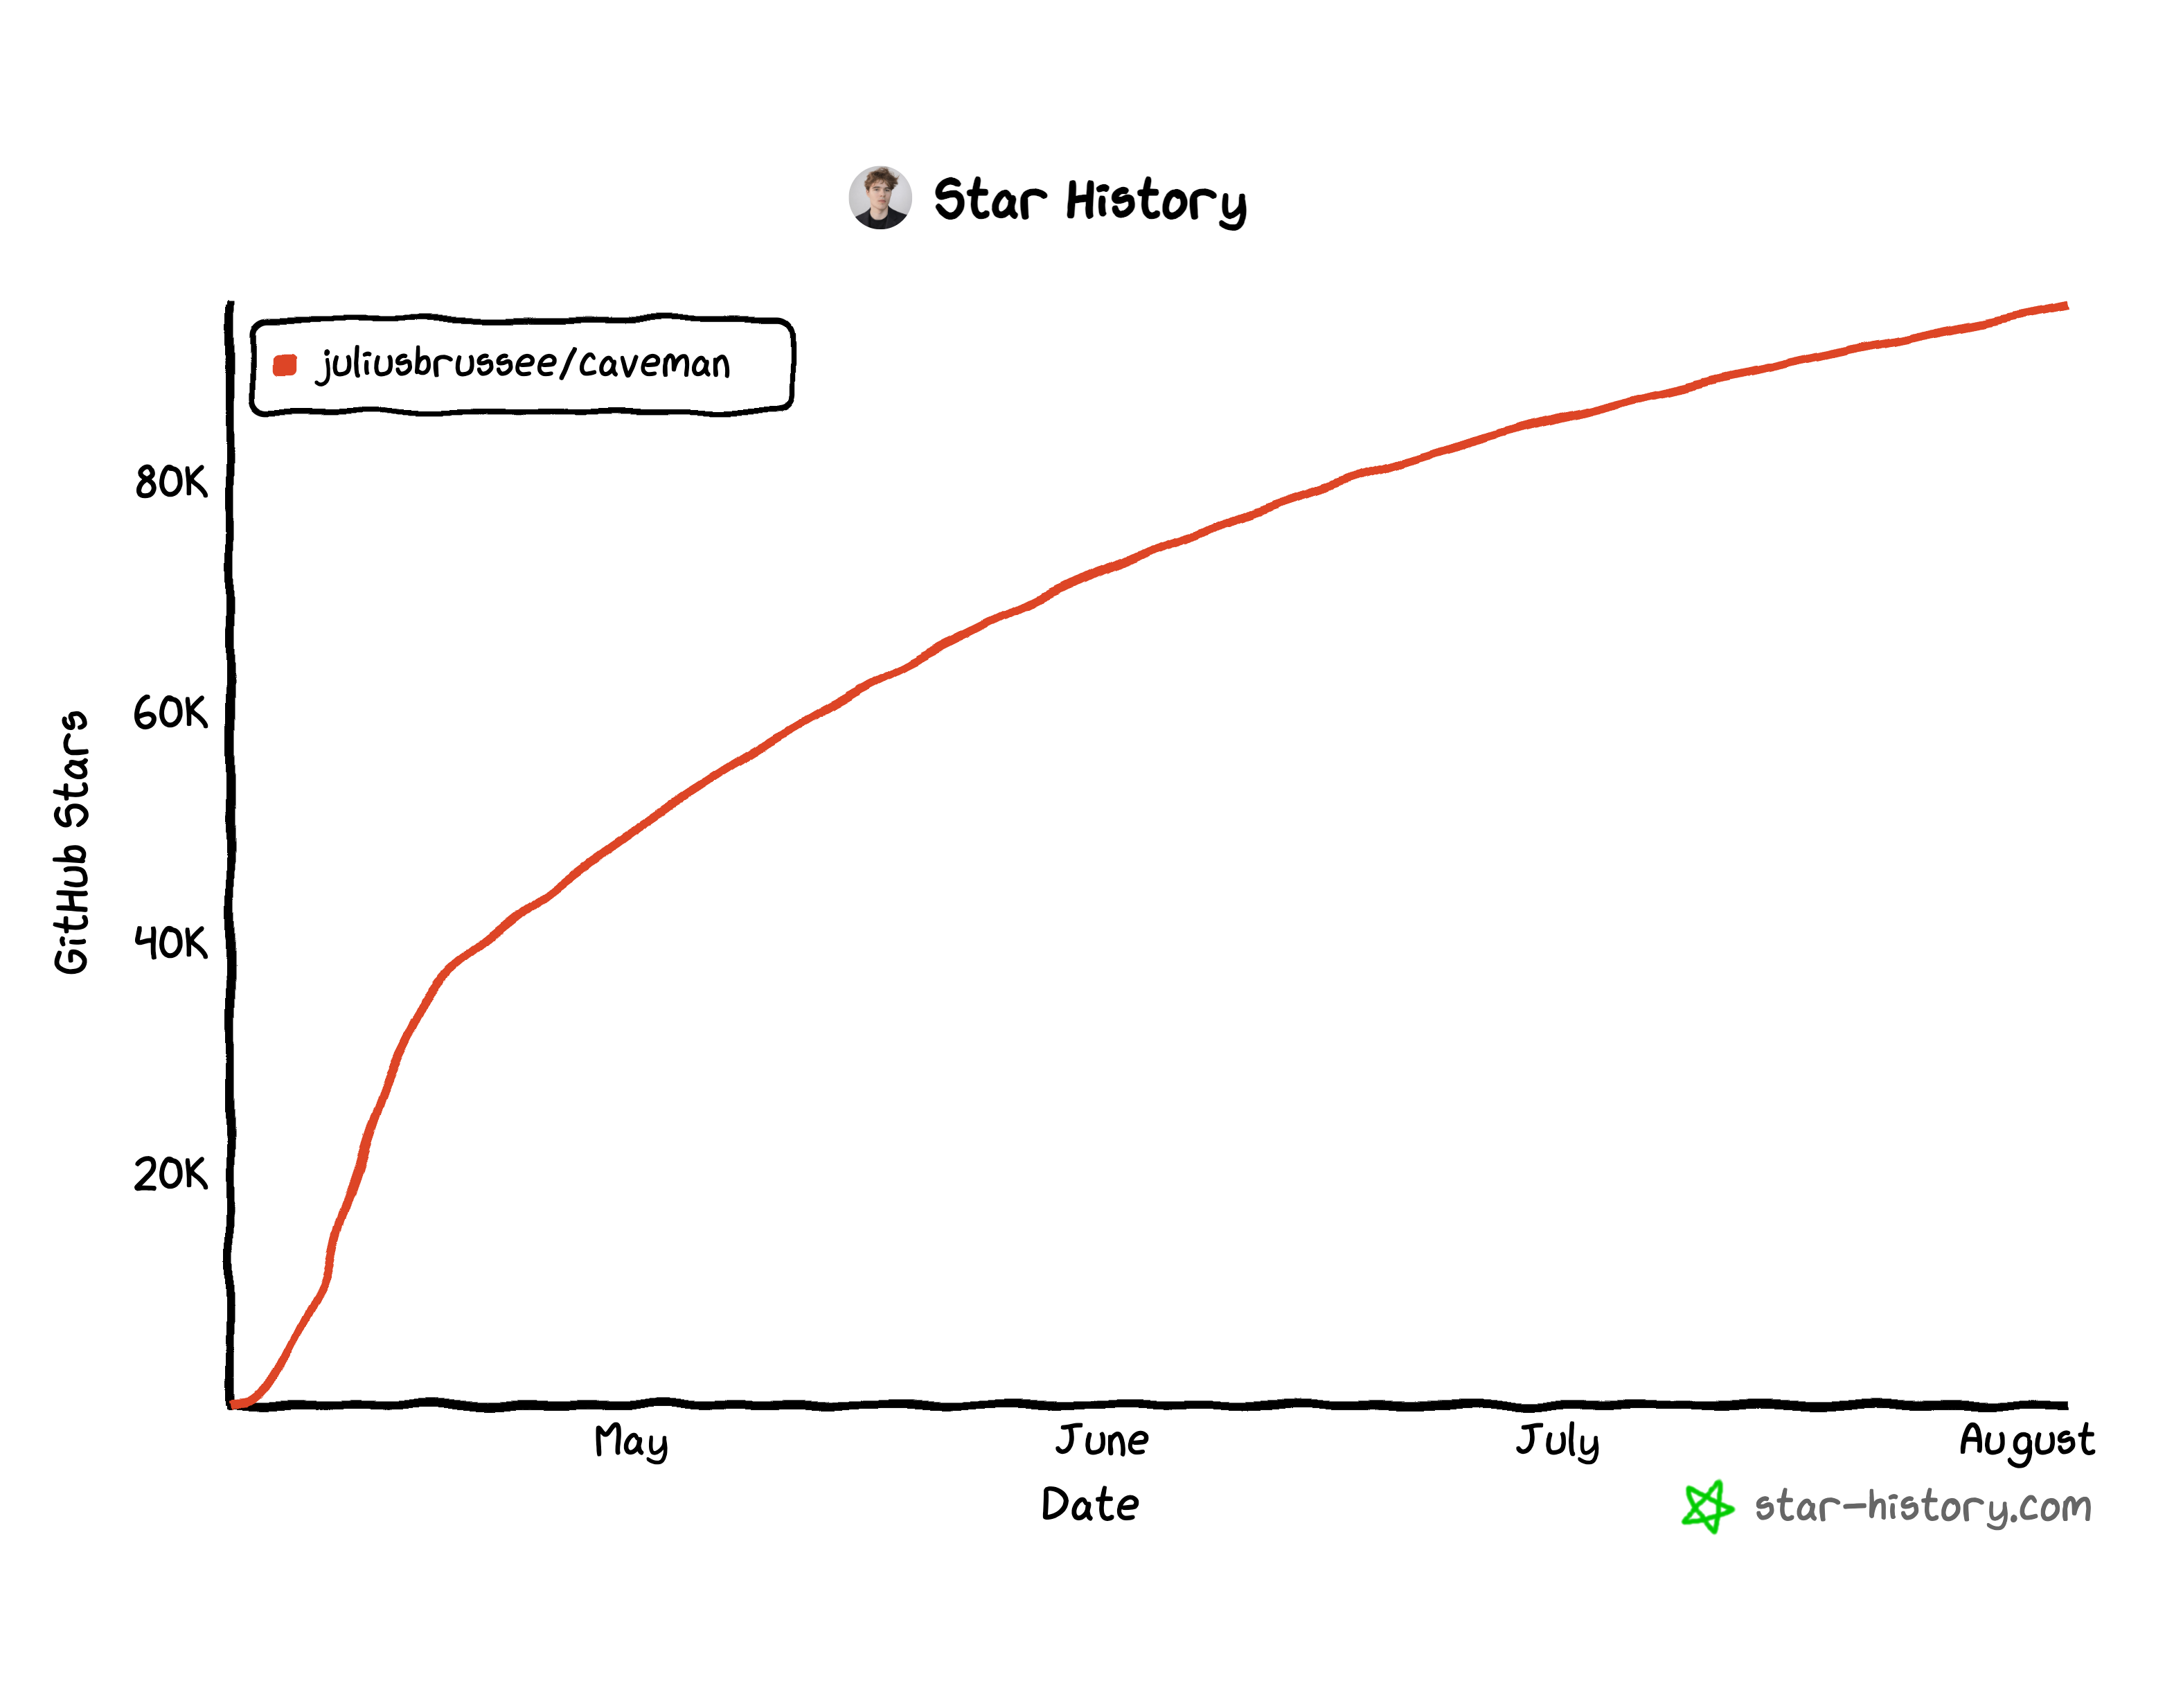
Started as a joke on a Friday in April 2026. Hit 4,000 stars in a week. Now past 100,000, with a research paper, a JetBrains lab test, and a Primeagen reaction video. The joke got serious. The voice did not.
⚡ Quick Start
Caveman come in two sizes. Start small.
Small rock: the skill
A rule file that makes your agent answer in caveman. Apache-2.0, free forever, works in 30+ agents (Claude Code, Codex, Gemini, Cursor, Windsurf, Cline, Copilot, more). One command:
npx skills add JuliusBrussee/caveman -gType /caveman if your agent doesn't wake up on its own. That the whole install. One rock.
Big rock: the proxy
Runs on your machine, between your agent and the AI provider, and shrinks what the agent reads before every call. Apache-2.0, CLI and runtime both:
npm install -g @caveman-ai/cli && caveman setup --install
caveman claude        # or codex · gemini · aider · kilo · qwen · opencode · hermes · openclaw · pi
Your own app: the middleware
Building an agent in code instead of running one in a terminal? Same shrinking, one wrapper around the call you already make. Apache-2.0 client, stable 1.0:
npm install @caveman-ai/middleware @caveman-ai/sdk        # TypeScript, plus your framework (ai, openai, …)
pip install 'caveman-middleware[langchain]' caveman-sdk   # Python 3.11+, swap the extra for your framework
Six lines of code and a local runtime. Full walkthrough below.
They stack. Most people start with the small rock and graduate.
More doors into the cave · full installer, Windows, single agents, uninstall
The full installer wires up Claude Code hooks and the statusline badge, finds every supported agent on your machine, and skips agents you no have. Safe to re-run. Needs Node.js 22.13+.
curl -fsSL https://raw.githubusercontent.com/JuliusBrussee/caveman/v3.0.0/install.sh | bashWindows, PowerShell 5.1+:
irm https://raw.githubusercontent.com/JuliusBrussee/caveman/v3.0.0/install.ps1 | iexJust one agent:
# Claude Code
claude plugin marketplace add JuliusBrussee/caveman && claude plugin install caveman@caveman

# Gemini CLI
gemini extensions install https://github.com/JuliusBrussee/caveman

# Oh My Pi (OMP)
npx -y github:JuliusBrussee/caveman -- --only omp

# Qwen Code CLI, then its Caveman wrapper
npm i -g @qwen-code/qwen-code
caveman qwen

# Codex, Cursor, Windsurf, Cline, and other skills-compatible agents
npx skills add JuliusBrussee/caveman --skill '*' -a codex --yes -g  # replace codex with your agent profile
Install broke? Open your agent in this repo and say: "Read CLAUDE.md and INSTALL.md, install caveman for me." Agent read repo, agent fix own brain. Snake eat tail.
Changed your mind: npx -y github:JuliusBrussee/caveman -- --uninstall
The full 30+ agent matrix, dry runs, flags, and verification live in INSTALL.md.
🕐 The first five minutes
Small rock. The skill, right after npx skills add:
- Ask it something. Any coding question. Watch the preamble vanish and the answer stay.
- Turn the dial.
/caveman litefor tight-but-polite./caveman ultrafor grunts./caveman wenyanfor classical Chinese, because someone asked. - Commit like a caveman.
/caveman-commitwrites a Conventional Commit in one line. - Review like a caveman.
/caveman-reviewgives one finding per line:L42: 🔴 null deref. Guard it. - Shrink your memory files.
/caveman-compress CLAUDE.mdcuts the prose, keeps every heading, path, and command, and backs up the original. - Come home. Say
stop caveman. Normal prose returns. No hard feelings.
Big rock. The proxy, right after npm install -g @caveman-ai/cli:
- Find out where your tokens go.
caveman learnreads months of agent history already on your disk, locally, and ranks the places your tokens go, biggest first, with a one-line fix behind each. Do this before anything else. It is the most useful five minutes in this README. After step 3 it keeps watching by itself and speaks up only when something new appears. - Let it fix them.
caveman learn implementhands each fix to Claude Code or Codex one diff at a time, applied only on your yes, and undoes anything that did not make each message smaller. - Wrap your agent.
caveman claude(orcodex,gemini,aider,opencode,pi, …) puts the proxy in front of it. Logs, test output, JSON, and diffs get shrunk before the provider sees them. Originals stay on disk, and the agent can pull any of them back. - Shrink the noisy stuff.
caveman shrink -- pnpm testcompresses command output.caveman browse <url>gives the agent a compressed view of a web page instead of a 15,000-token accessibility dump. - Prove it on your own work.
caveman trial -- clauderuns a real session with and without caveman, thencaveman trial reportshows the difference. That A/B outranks every number on this page. A trial needs its own proxy, so if you already did step 3 it will tell you to runcaveman disable claudefirst, andcaveman enable claudeafter. Caveman rather say "cannot measure this" than hand you a report full of zeros. - Shrink caveman itself.
caveman convert --dry-runshows which installed skills get cheaper as PNG pages the model reads as an image. Convert the profitable ones, revert byte-for-byte any time. - Watch the bill.
caveman statsfor history and estimates./caveman-statsinside Claude Code for that session.
📊 The Numbers
Every number below is either from a committed run in this repo or from a named third party. Nothing rounded up. Where a number is small, it says so. Where a row is red, it stays red.
What the skill saves (writing less)
| Who measured | What they measured | Result |
|---|---|---|
| Adobe Research (CAVEWOMAN, arXiv 2606.24083) | Eight models, five datasets, five compression levels | Output-side caveman style cuts realized cost 1.4 to 2.4× per model, up to 3× in the best case |
| JetBrains | 86 real coding tasks, paired A/B, Claude Code 2.1.200. Skill only, no proxy (July 2026, before the proxy existed) | 8.5% fewer output tokens, about 10% cost. No detectable quality change (sign test p = 0.82) |
| This repo (committed eval snapshot) | Ten dev questions, skill vs a plain Answer concisely. control, claude-opus-4-6 |
50% fewer output tokens at the median on top of the terse control. Length only, not correctness |
Read those three together and you get the honest picture. Chat-style Q&A: big cut. Agentic coding sessions, where most tokens are code and tool calls that the skill never touches: high single digits on output, quality flat.
The JetBrains number is why the proxy exists. They measured the skill alone, in July 2026, before the proxy shipped. Their finding was that an agent's bill is mostly reading, not writing, and no talking style fixes that. So we built the thing that shrinks the reading. The table below is what that changed.
The Adobe paper's other finding matters too: compressing the human's prompt into caveman-speak makes models answer longer and worse. Caveman never rewrites your prompts. Only the agent's mouth.
The rules add input tokens on every call, and whether shorter output pays for them depends on your agent, caching, and billing. Full accounting: docs/HONEST-NUMBERS.md.
No reviewed API benchmark result is published here yet. Run
uv run python benchmarks/run.py to generate a new result, then review its raw
response pairs and quality before publishing the generated table.
What the proxy saves (reading less)
Your agent rereads logs, test output, diffs, and half your repo all day. The proxy shrinks that stream before it reaches the provider. Pinned 54-run Claude Code benchmark, provider-reported input tokens, three runs per case, every answer checked against an exact oracle:
| Case | Direct Claude Code | Through caveman | Change |
|---|---|---|---|
| CSV outlier hunt | 165,823 | 74,484 | -55.1% |
| Log needle in haystack | 148,807 | 74,068 | -50.2% |
| YAML config drift | 132,124 | 71,027 | -46.2% |
| Test output failure | 150,377 | 108,514 | -27.8% |
| Deployment JSON drift | 147,975 | 108,939 | -26.4% |
| Dashboard HTML alert | 140,687 | 154,641 | +9.9% |
| Total | 885,793 | 591,673 | -33.2% |
18 of 18 answer checks passed. Case-clustered 95% interval: 14.6% to 48.5%. In the same suite, Headroom's wrap saved 6.7% and failed 3 of 18 checks. Method, provenance hashes, and limits: docs/WRAP-BENCHMARK.md. Raw harness artifacts are not in this checkout, so treat it as a pinned report, not a public reproduction.
Maintainer note. The HTML row is red and it stays red. That case had no compression transform, so caveman paid its own overhead and won nothing back. The day I hide a red row is the day you should stop trusting the green ones.
Everything else caveman shrinks
| Surface | Measured | Number |
|---|---|---|
| Browser pages | Focused question against a 200-row table, vs the Playwright ARIA snapshot | 121 tokens vs 15,704. 129.8× smaller. Tiny forms lose 2.3×; the benchmark says so |
Memory files (/caveman-compress) |
Five real CLAUDE.md-style fixtures |
46% smaller on average, headings, code, paths, and URLs verified intact |
| The skill itself (pixel mode) | Rendered to PNG pages the model reads as an image | 1,069 to 415 estimated tokens, a 61% cut |
Your harness prefix (subagent-tax) |
What every subagent re-sends before doing any work | On one real machine, 219k of a 267k-char request was tool schemas. Run it on yours |
🧮 How it compares
Many tool in valley promise small token. They work at different layers, so first what each one touches, then what got measured. Every quote below is from that tool's own README or GitHub page on 2026-09-19.
What each one touches
| Tool | What it shrinks | Get the original back? | Phones home |
|---|---|---|---|
| Caveman | What the agent says (skill) and what it reads: tool output, logs, JSON, diffs, test output, web pages (proxy) | Always. Byte-exact original in local SQLite, one recovery handle | CLI and its agent hooks: usage stats with a random install ID and your IP, on by default, caveman telemetry off. Skill alone: never |
| RTK | Shell command output only: ls, cat, grep, git, test runners. Read and Grep tool calls bypass it |
When a command fails or gets cut short, or opt-in for successful runs | Off by default, opt-in |
| Headroom | Tool output, logs, files, and history, through a local proxy | Yes, reversible cache | On by default, HEADROOM_BEACON=off |
| context-mode | Tool output, run in a sandbox so raw data never enters context | Matching sections from a searchable index, not the whole thing back | Never |
| pxpipe | Text context, re-rendered as images the model reads | No. "It is lossy." Misses are silent | Local log only |
What the tin says, and who checked
| Tool | Says on the tin | Who checked, on what | Found |
|---|---|---|---|
| Caveman | Only what this page measures | This repo, pinned 54-run Claude Code suite, every answer checked against a known-right answer | 33.2% fewer input tokens, 18/18 answers right |
| Caveman, skill only | JetBrains, 86 real coding tasks, paired A/B | 8.5% fewer output tokens, quality flat (sign test p = 0.82) | |
| RTK | "cuts up to 90% of the bash output your agent reads". Their README adds: "it is not the same as cutting your bill by 90%" | JetBrains, same lab, same method, 86 tasks, 425 billed trials | +7.6% median cost per task at low reasoning effort (p = 0.004), +0.1% at high. Quality tie |
| Headroom | "20% fewer tokens for coding agents, 60-95% fewer tokens for JSON" | This repo, same 54-run suite as above | 6.7% fewer input tokens, 15/18 answers right |
| context-mode | "315 KB becomes 5.4 KB. 98% reduction." | Own size numbers only. No quality check published | — |
| pxpipe | "~59–70% lower end-to-end bill" | Own SWE-bench runs | Lite 10/10 both arms. Pro 14/19 with, 15/19 without, and their rerun of the one split says run-to-run variance |
Same suite, same model, same questions
The one place two of these tools ran side by side against the same known-right answers. Claude Code 2.1.223, claude-sonnet-5, Headroom 0.33.0, six agent-shaped workloads, three runs each, provider-reported input tokens:
| Arm | Answers right | Provider input tokens | vs direct | 95% interval |
|---|---|---|---|---|
| Direct Claude Code | 18/18 | 885,793 | baseline | |
| Caveman wrap + skill | 18/18 | 591,673 | -33.2% | 14.6% to 48.5% |
| Headroom wrap | 15/18 | 703,202 on its 15 correct runs | -6.7% on those 15 | -0.7% to 17.9% |
Caveman used fewer tokens in 15 of the 18 paired runs. Headroom's 703,202 covers only the 15 runs it answered right, so its 6.7% is against those same 15 direct runs, not against the 885,793 total. Its three failed YAML runs stay in the table and count for nothing. Caveman's one red row, HTML at +9.9%, is in the per-case table above and stays red too. We ran this ourselves, and the raw harness artifacts are not published yet, so it is a pinned report, not something you can re-run from this repo. Method and hashes: docs/WRAP-BENCHMARK.md.
RTK, context-mode, and pxpipe were not in that run. RTK rewrites shell output, and this suite hands the agent its data through a tool call, not the shell, so RTK would have sat idle. Different layer, different test. Fair is fair on the rest: RTK's telemetry is opt-in and ours is opt-out, context-mode sends nothing anywhere, and pxpipe ran SWE-bench where we have not. Stack them if you like. Headroom's own README lists caveman as something it happily runs behind.
📣 In the Wild
|
ThePrimeagen · "No way this actually works" Adobe Research · CAVEWOMAN: How Large Language Models Behave Under Linguistic Input and Output Compression JetBrains · Speaking to AI Agents like Cavemen Saves 65% of Tokens. We Test. |
Hacker News · #1, 904 points, 366 comments The New Stack · Getting Claude Code to grunt in Caveman-speak might not save as many tokens as you think GitHub Trending · #1 overall, July 2026 Product Hunt · #8 Product of the Day |
💬 The skill, unpacked
One rule file, one talking style, plus a small toolbox. /caveman lite|full|ultra|wenyan-lite|wenyan-full|wenyan-ultra sets intensity. /caveman off or normal mode turns it off.
| Level | Same question: "Why does my React component re-render?" |
|---|---|
| lite | Your component re-renders because you create a new object reference each render. Wrap it in useMemo. |
| full (default) | New object ref each render. Inline object prop = new ref = re-render. Wrap in useMemo. |
| ultra | Inline obj prop, new ref, re-render. useMemo. |
| wenyan-full | 每繪新生對象參照,故重繪;以 useMemo 包之則免。 |
Three things the skill will never do: shorten your code, paraphrase an error message, or grunt through a security warning. It drops to full sentences for anything irreversible, then picks the club back up.
Everything in the box · commit messages, reviews, subagents, work patterns
| Tool / command | What you get |
|---|---|
/caveman [lite|full|ultra|wenyan-lite|wenyan-full|wenyan-ultra|off] |
Shorter replies at the intensity you choose. |
cavecrew-investigator, cavecrew-builder, cavecrew-reviewer |
Compressed subagent presets for locating, editing, and reviewing code. |
/caveman-commit |
Terse Conventional Commit messages. |
/caveman-review |
One-line, actionable review findings. |
/caveman-compress <file> |
Smaller Markdown memory files, with the original backed up. |
/caveman-stats |
Recorded Claude Code token usage; savings unknown without a measured comparison. |
/caveman-help |
One-screen reminder of every mode and command. |
investigate-first, lean-build, surgical-patch, safe-refactor, migration, verify-and-stop |
Work patterns that write less code, so the agent bills fewer tokens. Your agent picks these up on its own when a task fits. |
/caveman-setup, /caveman-discover, /caveman-learn, /caveman-manage, /caveman-optimize, /caveman-explore, /caveman-evidence-review |
Drive the caveman engine and proxy: set it up, find where tokens go, act on what it finds. |
🔧 The proxy, unpacked
One local process. Your agent talks to it, it talks to your provider. No Caveman server in the path, and your Claude Pro/Max login passes through to Anthropic untouched. Originals of everything it compresses sit in a SQLite file on your machine with a recovery handle, so the agent can always ask for the full version back.
 Your agent  (Claude Code · Codex · Gemini · Aider · opencode · Pi · …)
      │   tool output · logs · JSON · diffs · search results
      ▼
 ┌────────────────────────────────────────────────────┐
 │  caveman proxy   (your machine, your keys)          │
 │  detect() → json · log · code · diff · search · text│
 │  originals → local SQLite, recovery handle returned │
 └────────────────────────────────────────────────────┘
      │   smaller prompt, same answer
      ▼
 Your provider  (Anthropic · OpenAI · Google · Bedrock · Vertex · Azure · OpenRouter)
Whole team? One container. Same proxy in your VPC, one shared token, keys stay on server. Deploy it →

What the engine keeps, by payload type · and the wrap stack diagram

detect() types each payload and routes it to a compressor that keeps what answers depend on:
| Detected type | Keeps | Target savings |
|---|---|---|
json |
keys, structure, error/message subtrees; collapses repetitive arrays | 70-90% |
log |
errors, stack traces, first/last lines; drops INFO and progress noise | 85-95% |
code |
imports, signatures, types; elides function bodies, syntax stays valid | 40-70% |
diff |
file/hunk headers and changed lines; elides repeated context | 60-80% |
search-result |
top/bottom hits plus diagnostic/security hits | 80-95% |
text / HTML |
headings, opening/closing context, important sections | 50-80% |
contextwindow.Pack() additionally fits candidate context into a token budget by BM25 relevance, recency, and error signal, returned in original order so chronology survives.
Any MCP host gets the same powers through five tools: caveman_compress, caveman_retrieve, caveman_stats, caveman_toon_encode, caveman_toon_decode.
Where your tokens go
Months of your agent history already sit on your disk. caveman learn reads it, locally, read-only, no account, and ranks the places your tokens go, biggest first, with a one-line fix behind each. Then it keep watching, so you not have to remember.
Your agent re-sends its instructions (CLAUDE.md, skills, hooks) and the whole conversation with every message it sends the model. So a few hundred extra tokens in a setup file get paid again on every single message. That is what learn hunts.
caveman learn             # Claude Code + Codex + Gemini CLI + opencode; aider via CAVEMAN_AIDER_ROOT
caveman learn implement   # hand the fixes to Claude Code or Codex, one diff at a time, applied only on your yes

It run itself. Once caveman is on your agent (caveman claude, caveman codex, …), learn re-scans quietly after a session ends. Low priority, at most every 6 hours, never makes the session wait. When something new and heavy shows up, your next session opens with one line, one time:
caveman learn: new finding — Project CLAUDE.md is 423 lines (~9,699 tokens), loaded with every message (~9.7k tokens in every message, estimate). Run `caveman learn` to review.
Nothing new, nothing said. caveman learn autopilot off if you rather run it by hand.
It check your memory files. Claude Code loads only the first 200 lines (or 25KB) of MEMORY.md. Everything past that, your agent never sees, and nothing tells you. Learn tells you. It also catches @imports pointing at files that are gone, the same rule pasted into two files your agent loads (you pay for it twice, every message), file paths in CLAUDE.md that no longer exist, and memory notes the index forgot to link.
It say if you getting better. Week over week, from your own sessions, first run included. Real output from the maintainer's machine, bad news left in:
last 6 weeks  tokens per session   ▄▂▃▁█┊▄  +185% · worse
              peak context used    ▁▁▄▅█┊▁  +4 points · worse
              overloaded messages  ▁▂▃▇█┊▅  +2.9 points · worse
              week of Sep 21 (928 sessions) vs the 4 weeks before
              a trend is not a saving, and it does not show the cause
"Overloaded" means the conversation filled more than half of what the model can hold at once. Past that, answers tend to get worse (a common rule of thumb). Each week counts its middle session, not the average, so one giant session can't skew it. Weeks under 5 sessions say "not enough data" instead of guessing. The ┊ marks the week still running: shown, never compared.
It prove the fix, or undo it. implement re-measures after every change and undoes anything that didn't make each message smaller. Some fixes can't be re-counted, like a new skill that only pays off when it gets used. For those, caveman learn experiment runs it on for a stretch and off for a stretch over your own sessions, and gives no verdict before 5 sessions each way. Caveman never makes your agent dumber to make it cheaper.
Every verb, every check, every number it will and won't show: docs/technical/learn.md.
More verbs
caveman explore install         # read-only FastContext subagent: finds code as path:line
caveman shrink -- pnpm test     # compress noisy command output, byte-exact recoverable
caveman browse <url>            # local Chrome over a compressed a11y tree
caveman mem remember|recall     # durable memory; `mem recover <handle>` = original bytes
caveman trial -- claude         # A/B a real session, then `trial report` (needs `disable` first)
caveman toon encode|decode      # the TOON re-encoder, standalone
caveman stats                   # token history, API estimates, subscription equivalents
Pixel mode
Caveman eating its own tail. Every skill you install is prompt text your agent reloads on every call. caveman convert renders the skill body to PNG pages in place, and the model reads it as an image. On the caveman skill itself: 1,069 to 415 estimated tokens, a 61% cut.
caveman convert --dry-run        # every installed skill, with the token math, no writes
caveman convert --agent claude   # convert the profitable ones
caveman convert --revert         # byte-identical restore from SKILL.orig.md
Convert only fires when pages beat the text. Any failure leaves the skill byte-identical and names the gate that said no.
Wrap any agent
caveman <agent> turns the proxy on for good and launches the agent. caveman wrap <agent> runs one session and leaves nothing behind. It never edits your config files.
In managed mode the Claude Code wrap also sends the repository (github.com owner/name) and current branch name as x-cave-tags, so Cloud can join a session's spend to the change it shipped. Branch names can carry a person's or customer's name. Not OK? Set CAVEMAN_WORK_TAGS=0 and no tags go. Or set your own x-cave-tags in ANTHROPIC_CUSTOM_HEADERS: the wrap sends yours exactly as written and adds nothing.
| Agent | Vendor | How it's wrapped |
|---|---|---|
| Claude Code | Anthropic | env vars |
| OpenAI Codex CLI | OpenAI | env vars (API key) · ephemeral CODEX_HOME (ChatGPT login) |
| Gemini CLI | env vars | |
| Aider | OpenAI/Anthropic | env vars |
| Kilo Code | Kilo Code | KILO_CONFIG_CONTENT, your kilo.json untouched |
| Qwen Code | QwenLM | ephemeral system-settings overlay, source settings untouched |
| opencode | sst | inline config via env, your opencode.json untouched |
| Hermes Agent | Nous Research | --provider custom + env |
| OpenClaw | OpenClaw | ephemeral merged config, your config read-only |
| Pi | pi.dev | bundled native extension, your ~/.pi config untouched |
Fine print · tested versions, default loadout, SDK recipes
Tested against real sessions on Hermes v0.18.0, OpenClaw 2026.6.11, Pi 0.84.2, Kilo Code 7.5.6 (the CLI, not the editor extension), and Qwen Code 0.22.3. Persistent shortcuts are journaled and reversible with caveman disable <agent>.
OpenClaw, for the record, is a lobster. Lobster claw still sharp. Lobster mouth now small.
The default wrap hands the agent the five MCP tools, the browse server when Chrome resolves, command-output shrink on Claude, opencode, Gemini, Hermes, and OpenClaw, and pixel mode on new skill installs. Codex skips the shrink hook because its runtime rejects the rewrite (openai/codex#18491). Turn pieces off in ~/.caveman-cloud/config.json.
Agent not on the list, or building your own? Wrap one call natively with the middleware, or point any provider SDK or framework (Vercel AI SDK, LangChain, LiteLLM, OpenAI Agents, CrewAI, PydanticAI) at the local proxy with a baseURL swap: integrations/recipes/. New native agent is usually one JSON profile in agents/profiles/.
🧩 Caveman in your own app
The proxy shrinks what a coding agent reads. The middleware does the same thing for the agent you are building, in the framework you already use. One wrapper around one call. Before each provider request it swaps big tool results for a shorter copy and hands the model a caveman_retrieve tool, so the model can read the original back whenever the short copy is not enough. Your conversation history keeps every original byte. Your provider, your client, your retries, your streaming: untouched.
TypeScript (Vercel AI SDK shown):
+import { createMiddlewareRuntime } from "@caveman-ai/sdk/middleware";
+import { withCaveman } from "@caveman-ai/middleware/ai-sdk";
+
+const runtime = createMiddlewareRuntime({ endpoint: "http://127.0.0.1:8787", mode: "compress" });
+const scope = { namespace: "support", session_id: conversationId, branch_id: "main", cache_epoch: "0" };
+
-const result = streamText(options);
+const result = streamText(withCaveman(options, { runtime, scope }));
Python (LangChain shown):
+from caveman_cloud.middleware import MiddlewareRuntime, Scope
+from caveman_middleware.langchain import with_caveman_agent
+
+runtime = MiddlewareRuntime(endpoint="http://127.0.0.1:8787", mode="compress")
+scope = Scope("support", conversation_id, "main", "0")
+
-agent = create_agent(model=model, tools=tools)
+agent = create_agent(**with_caveman_agent({"model": model, "tools": tools}, runtime=runtime, scope=scope))
The runtime is the same local proxy from the big rock, started once beside your app:
npm install -g @caveman-ai/cli && caveman setup --install
CAVEMAN_MODE=compress caveman start # binds 127.0.0.1:8787; plain `caveman start` only records| Frameworks with a native adapter | |
|---|---|
TypeScript @caveman-ai/middleware |
Vercel AI SDK · OpenAI · Anthropic · Google GenAI · LangChain · Strands · Mastra · MCP |
Python caveman-middleware |
OpenAI · Anthropic · Google GenAI · LangChain + LangGraph · LiteLLM · Strands · Agno · CrewAI · PydanticAI · AutoGen · LlamaIndex · FastAPI · MCP |
Straight talk: a runtime left in record mode measures and changes nothing, whichever mode the client asks for, so set both. Decision reports say what was replaced and why, and carry no token counters; provider usage is the only savings number that counts. Runtime unreachable means your original request goes through untouched, unless you opt into strict mode.
Docs: middleware overview · Vercel AI SDK guide · Python guide · every framework and version · deploy beside your app · package READMEs for TypeScript and Python.
Rather not touch code? Point any SDK at the proxy with a baseURL swap instead: integrations/recipes/.
🧭 When to use · when to skip
Good fit if you read your agent's answers more than you paste them somewhere, run long sessions full of logs and test output, or pay per token and want the reading side shrunk without changing your code.
Skip it if you are billed per request rather than per token (GitHub Copilot premium requests, for one: a shorter answer is the same request), or your workload is pure code generation with almost no prose to cut. The ruleset rides along as input tokens on every call (about 1,000 estimated for the full skill), and on terse one-liner Q&A that can cost more than it saves.
Measure it yourself. Run the same task with and without caveman and compare the provider's billing page. That A/B outranks every number on this page. If caveman loses on your workload, turn it off. Full list of where it loses: docs/HONEST-NUMBERS.md.
🏔 The whole cave
One idea everywhere: agent do more with less.
| Repo | What it shrinks | Status |
|---|---|---|
| caveman (you here) | What the agent says (skill), reads (proxy), and what your own app sends (middleware) | live |
| caveman-browse | What the agent sees in the browser | live |
| caveman-agent-sdk | What your production agent loads, calls, and spends | own repo · in dev |
| cavegemma | The compression baked into weights (Gemma fine-tune) | labs |
| caveman-code | The whole agent, end to end | frozen |
| cavemem | What the agent remembers, across sessions | frozen |
| cavekit | The build loop, spec-driven | frozen |
Frozen ones still install and work. Their best ideas moved in here.
Caveman make token small. Caveman Cloud make it provable. Local numbers are inferred, pinned benchmarks benchmark_counterfactual, neither is an invoice. Live traffic behind eval gates with signed receipts earns verified. That's Cloud. Waitlist at caveman.so
🔒 Privacy, and a small favor
Your agent still talks to the provider you chose. The skill runs entirely on your machine, and nothing here needs an account.
The caveman CLI does send usage stats by default, and here's the honest why: caveman is free, one person maintains it, and those stats are how I find out which commands people actually use and which optimizations run in real workflows. That's what keeps this thing free and pointed in the right direction. Fair trade, we think.
What it sends: which commands ran, when your agent starts a session (the CLI's agent hooks send that one), token counts through and cut, a random install ID, your OS and CLI version, whether you're signed in, how you installed it, your timezone and language, and the IP address the stats come from. IPs get wiped after 90 days, everything else after 13 months. What it never sends: your prompts, your code, or your file paths. It tells you all this the first time you run it.
Not into it? One command and it's off forever, no hard feelings:
caveman telemetry off # or set DO_NOT_TRACK=1Want what it already sent gone too? telemetry off prints your install ID one last time. Send it to us and we delete it all. How: SECURITY.md.
Exact network, telemetry, and storage boundaries: SECURITY.md.
📜 License
One license: Apache-2.0, whole repo, from Caveman 3.0.0 on. Skill, CLI, client SDKs, middleware, contracts, provider catalog, extension, and the full runtime: Engine, Proxy, Browse, MCP server, shrink, cavemem, shared Go platform. Read it, fork it, ship it, host it. Free like mammoth on open plain.
Releases before 3.0.0 keep the license they shipped with. Details in LICENSING.md.
engine/pixel embeds pxpipe (MIT) plus glyph atlases derived from Spleen 5×8 (BSD-2-Clause) and GNU Unifont (dual OFL-1.1 / GPLv2-with-font-exception); its NOTICE travels with that source.
"Caveman" and the rock logo are trademarks of Julius Brussee. "Powered by Caveman" is fine when true.
📚 Cite
If caveman shows up in your paper, the way it showed up in Adobe's:
@software{brussee2026caveman,
  author = {Brussee, Julius},
  title  = {Caveman: why use many token when few do trick},
  year   = {2026},
  url    = {https://github.com/JuliusBrussee/caveman}
}
⭐ Star this repo
Caveman save you token, save you money. Star cost zero. Fair trade. ⭐
Docs: Technical manual · Install matrix · Honest numbers · Wrap benchmark · License · Contributing · Maintainer guide · Issues
One license, Apache-2.0. Few token. No lie.
