MakazhanAlpamys/SoupPublic

Fine-tune LLMs from one YAML. Layer streaming trains an 8B model on a 4 GB laptop GPU.

AI summary: A lightning-fast, C++ based LLM fine-tuning CLI that utilizes layer streaming.

Stars
9.6K
+90 today
Forks
1.6K
Watchers
59
Open issues
119
Open PRs
71
Contributors
~111
Commits
1.9K
Branches
23

PythonApache-2.0Created Feb 20, 2026Last push 1d agoLatest release v0.76.1+455 stars this week+2.6K this month

Quick answers

What is Soup?
A lightning-fast, C++ based LLM fine-tuning CLI that utilizes layer streaming.
What does Soup do?
Soup is a highly optimized Command Line Interface tool designed for fine-tuning Large Language Models on consumer-grade hardware. It achieves remarkable efficiency by utilizing a C++ backend and a novel technique called 'layer streaming', which significantly reduces the VRAM required to train massive models. The tool is designed to provide an incredibly fast, lightweight alternative to heavy Python-based training frameworks, making it possible to run sophisticated parameter-efficient fine-tuning (PEFT) on standard desktop GPUs. It strips away complex dependencies to focus entirely on raw execution speed and memory optimization.
Who is Soup for?
This tool is intended for machine learning engineers, AI researchers, and developers who need to fine-tune LLMs but are restricted by consumer hardware. Users should have a strong understanding of command-line tools and LLM training concepts.
How do I get started with Soup?
git clone https://github.com/MakazhanAlpamys/Soup.git
How popular is Soup on GitHub?
MakazhanAlpamys/Soup has 9,621 stars and 1,572 forks on GitHub, and gained 455 stars in the last 7 days.
What license does Soup use?
MakazhanAlpamys/Soup is released under the Apache-2.0 license.

Star history

since Aug 16, 2026
02.5K5K7.5KAug 2026Sep 2026Sep 2026Oct 2026
9.6K stars as of Oct 24, 2026. Measured daily since Aug 16, 2026; GitHub no longer exposes earlier star timestamps.

Update history

1 recorded
  • Oct 16, 2026New release v0.76.1 (previously v0.75.2).

Contribution activity

commits per day, last 52 weeks
OctNovDecJanFebMarAprMayJunJulAugSepOctMonWedFri2025-10-18: 0 commits2025-10-19: 0 commits2025-10-20: 0 commits2025-10-21: 0 commits2025-10-22: 0 commits2025-10-23: 0 commits2025-10-24: 0 commits2025-10-25: 0 commits2025-10-26: 0 commits2025-10-27: 0 commits2025-10-28: 0 commits2025-10-29: 0 commits2025-10-30: 0 commits2025-10-31: 0 commits2025-11-01: 0 commits2025-11-02: 0 commits2025-11-03: 0 commits2025-11-04: 0 commits2025-11-05: 0 commits2025-11-06: 0 commits2025-11-07: 0 commits2025-11-09: 0 commits2025-11-10: 0 commits2025-11-11: 0 commits2025-11-12: 0 commits2025-11-13: 0 commits2025-11-14: 0 commits2025-11-15: 0 commits2025-11-16: 0 commits2025-11-17: 0 commits2025-11-18: 0 commits2025-11-19: 0 commits2025-11-20: 0 commits2025-11-21: 0 commits2025-11-22: 0 commits2025-11-23: 0 commits2025-11-24: 0 commits2025-11-25: 0 commits2025-11-26: 0 commits2025-11-27: 0 commits2025-11-28: 0 commits2025-11-29: 0 commits2025-11-30: 0 commits2025-12-01: 0 commits2025-12-02: 0 commits2025-12-03: 0 commits2025-12-04: 0 commits2025-12-05: 0 commits2025-12-06: 0 commits2025-12-07: 0 commits2025-12-08: 0 commits2025-12-09: 0 commits2025-12-10: 0 commits2025-12-11: 0 commits2025-12-12: 0 commits2025-12-13: 0 commits2025-12-14: 0 commits2025-12-15: 0 commits2025-12-16: 0 commits2025-12-17: 0 commits2025-12-18: 0 commits2025-12-19: 0 commits2025-12-20: 0 commits2025-12-21: 0 commits2025-12-22: 0 commits2025-12-23: 0 commits2025-12-24: 0 commits2025-12-25: 0 commits2025-12-26: 0 commits2025-12-27: 0 commits2025-12-28: 0 commits2025-12-29: 0 commits2025-12-30: 0 commits2025-12-31: 0 commits2026-01-01: 0 commits2026-01-02: 0 commits2026-01-03: 0 commits2026-01-04: 0 commits2026-01-05: 0 commits2026-01-06: 0 commits2026-01-07: 0 commits2026-01-08: 0 commits2026-01-09: 0 commits2026-01-10: 0 commits2026-01-11: 0 commits2026-01-12: 0 commits2026-01-13: 0 commits2026-01-14: 0 commits2026-01-15: 0 commits2026-01-16: 0 commits2026-01-17: 0 commits2026-01-18: 0 commits2026-01-19: 0 commits2026-01-20: 0 commits2026-01-21: 0 commits2026-01-22: 0 commits2026-01-23: 0 commits2026-01-24: 0 commits2026-01-25: 0 commits2026-01-26: 0 commits2026-01-27: 0 commits2026-01-28: 0 commits2026-01-29: 0 commits2026-01-30: 0 commits2026-01-31: 0 commits2026-02-01: 0 commits2026-02-02: 0 commits2026-02-03: 0 commits2026-02-04: 0 commits2026-02-05: 0 commits2026-02-06: 0 commits2026-02-07: 0 commits2026-02-08: 0 commits2026-02-09: 0 commits2026-02-10: 0 commits2026-02-11: 0 commits2026-02-12: 0 commits2026-02-13: 0 commits2026-02-14: 0 commits2026-02-15: 0 commits2026-02-16: 0 commits2026-02-17: 0 commits2026-02-18: 0 commits2026-02-19: 0 commits2026-02-20: 5 commits2026-02-21: 0 commits2026-02-22: 0 commits2026-02-23: 3 commits2026-02-24: 1 commit2026-02-25: 0 commits2026-02-26: 0 commits2026-02-27: 0 commits2026-02-28: 0 commits2026-03-01: 0 commits2026-03-02: 5 commits2026-03-03: 3 commits2026-03-04: 2 commits2026-03-05: 10 commits2026-03-06: 0 commits2026-03-07: 0 commits2026-03-08: 0 commits2026-03-09: 0 commits2026-03-10: 0 commits2026-03-11: 0 commits2026-03-12: 0 commits2026-03-13: 0 commits2026-03-14: 0 commits2026-03-15: 0 commits2026-03-16: 0 commits2026-03-17: 0 commits2026-03-18: 0 commits2026-03-19: 0 commits2026-03-20: 0 commits2026-03-21: 0 commits2026-03-22: 0 commits2026-03-23: 29 commits2026-03-24: 20 commits2026-03-25: 26 commits2026-03-26: 20 commits2026-03-27: 0 commits2026-03-28: 0 commits2026-03-29: 0 commits2026-03-30: 0 commits2026-03-31: 0 commits2026-04-01: 24 commits2026-04-02: 3 commits2026-04-03: 10 commits2026-04-04: 3 commits2026-04-05: 2 commits2026-04-06: 1 commit2026-04-07: 6 commits2026-04-08: 0 commits2026-04-09: 0 commits2026-04-10: 2 commits2026-04-11: 0 commits2026-04-12: 0 commits2026-04-13: 5 commits2026-04-14: 0 commits2026-04-15: 2 commits2026-04-16: 0 commits2026-04-17: 0 commits2026-04-18: 0 commits2026-04-19: 4 commits2026-04-20: 5 commits2026-04-21: 3 commits2026-04-22: 3 commits2026-04-23: 3 commits2026-04-24: 3 commits2026-04-25: 2 commits2026-04-26: 2 commits2026-04-27: 13 commits2026-04-28: 5 commits2026-04-29: 0 commits2026-04-30: 3 commits2026-05-01: 4 commits2026-05-02: 0 commits2026-05-03: 2 commits2026-05-04: 1 commit2026-05-05: 0 commits2026-05-06: 0 commits2026-05-07: 0 commits2026-05-08: 7 commits2026-05-09: 8 commits2026-05-10: 6 commits2026-05-11: 8 commits2026-05-12: 5 commits2026-05-13: 14 commits2026-05-14: 9 commits2026-05-15: 12 commits2026-05-16: 0 commits2026-05-17: 2 commits2026-05-18: 4 commits2026-05-19: 5 commits2026-05-20: 6 commits2026-05-21: 2 commits2026-05-22: 1 commit2026-05-23: 0 commits2026-05-24: 4 commits2026-05-25: 4 commits2026-05-26: 3 commits2026-05-27: 1 commit2026-05-28: 0 commits2026-05-29: 0 commits2026-05-30: 1 commit2026-05-31: 3 commits2026-06-01: 11 commits2026-06-02: 5 commits2026-06-03: 9 commits2026-06-04: 9 commits2026-06-05: 3 commits2026-06-06: 4 commits2026-06-07: 5 commits2026-06-08: 3 commits2026-06-09: 3 commits2026-06-10: 6 commits2026-06-11: 0 commits2026-06-12: 1 commit2026-06-13: 0 commits2026-06-14: 0 commits2026-06-15: 0 commits2026-06-16: 0 commits2026-06-17: 0 commits2026-06-18: 0 commits2026-06-19: 0 commits2026-06-20: 3 commits2026-06-21: 1 commit2026-06-22: 3 commits2026-06-23: 0 commits2026-06-24: 0 commits2026-06-25: 0 commits2026-06-26: 0 commits2026-06-27: 1 commit2026-06-28: 3 commits2026-06-29: 0 commits2026-06-30: 0 commits2026-07-01: 8 commits2026-07-02: 6 commits2026-07-03: 3 commits2026-07-04: 16 commits2026-07-05: 40 commits2026-07-06: 17 commits2026-07-07: 5 commits2026-07-08: 3 commits2026-07-09: 0 commits2026-07-10: 0 commits2026-07-11: 0 commits2026-07-12: 9 commits2026-07-13: 3 commits2026-07-14: 0 commits2026-07-15: 15 commits2026-07-16: 21 commits2026-07-17: 8 commits2026-07-18: 0 commits2026-07-19: 8 commits2026-07-20: 0 commits2026-07-21: 0 commits2026-07-22: 0 commits2026-07-23: 0 commits2026-07-24: 0 commits2026-07-25: 0 commits2026-07-26: 1 commit2026-07-27: 3 commits2026-07-28: 9 commits2026-07-29: 1 commit2026-07-30: 0 commits2026-07-31: 1 commit2026-08-01: 5 commits2026-08-02: 0 commits2026-08-03: 9 commits2026-08-04: 3 commits2026-08-05: 12 commits2026-08-06: 25 commits2026-08-07: 39 commits2026-08-08: 23 commits2026-08-09: 23 commits2026-08-10: 1 commit2026-08-11: 9 commits2026-08-12: 3 commits2026-08-13: 13 commits2026-08-14: 15 commits2026-08-15: 14 commits2026-08-16: 16 commits2026-08-17: 11 commits2026-08-18: 17 commits2026-08-19: 12 commits2026-08-20: 15 commits2026-08-21: 9 commits2026-08-22: 15 commits2026-08-23: 20 commits2026-08-24: 21 commits2026-08-25: 12 commits2026-08-26: 10 commits2026-08-27: 18 commits2026-08-28: 14 commits2026-08-29: 6 commits2026-08-30: 4 commits2026-08-31: 21 commits2026-09-01: 16 commits2026-09-02: 20 commits2026-09-03: 19 commits2026-09-04: 12 commits2026-09-05: 21 commits2026-09-06: 20 commits2026-09-07: 14 commits2026-09-08: 4 commits2026-09-09: 14 commits2026-09-10: 10 commits2026-09-11: 17 commits2026-09-12: 22 commits2026-09-13: 28 commits2026-09-14: 48 commits2026-09-15: 33 commits2026-09-16: 8 commits2026-09-17: 25 commits2026-09-18: 25 commits2026-09-19: 16 commits2026-09-20: 0 commits2026-09-21: 15 commits2026-09-22: 24 commits2026-09-23: 7 commits2026-09-24: 22 commits2026-09-25: 23 commits2026-09-26: 9 commits2026-09-27: 34 commits2026-09-28: 35 commits2026-09-29: 18 commits2026-09-30: 30 commits2026-10-01: 34 commits2026-10-02: 7 commits2026-10-03: 0 commits2026-10-04: 14 commits2026-10-05: 27 commits2026-10-06: 20 commits2026-10-07: 39 commits2026-10-08: 44 commits2026-10-09: 13 commits2026-10-10: 2 commits2026-10-11: 0 commits2026-10-12: 17 commits2026-10-13: 21 commits2026-10-14: 24 commits2026-10-15: 22 commits2026-10-16: 16 commits2026-10-17: 0 commits
1,891 commits in the last yearLessMore

Signals and awards

derived from tracked data
  • Very active

    1,891 commits in 52 weeks

  • Community-driven

    ~111 contributors

  • Well documented

    High community health score

  • Permissive license

    Apache-2.0

  • Continuous integration

    Automated checks passing

  • Repeat trending

    8 trending appearances

What Soup does

Soup is a highly optimized Command Line Interface tool designed for fine-tuning Large Language Models on consumer-grade hardware. It achieves remarkable efficiency by utilizing a C++ backend and a novel technique called 'layer streaming', which significantly reduces the VRAM required to train massive models. The tool is designed to provide an incredibly fast, lightweight alternative to heavy Python-based training frameworks, making it possible to run sophisticated parameter-efficient fine-tuning (PEFT) on standard desktop GPUs. It strips away complex dependencies to focus entirely on raw execution speed and memory optimization.

This tool is intended for machine learning engineers, AI researchers, and developers who need to fine-tune LLMs but are restricted by consumer hardware. Users should have a strong understanding of command-line tools and LLM training concepts.

  • Layer Streaming Architecture: Streams model layers on demand to drastically minimize the continuous VRAM footprint during training.
  • C++ Optimization: Built entirely in C++ to strip out Python overhead and maximize raw computational performance.
  • Hardware Accessibility: Enables parameter-efficient fine-tuning of massive LLMs on standard, consumer-grade desktop GPUs.
  • CLI Driven: Provides a lean, highly focused command-line interface without the bloat of massive training platforms.
  • Lightweight Footprint: Achieves lightning-fast startup and execution times by aggressively minimizing external dependencies.

Where teams use it

Consumer Hardware Fine-Tuning

AI hobbyists and independent developers use the tool to fine-tune large language models directly on their personal gaming PCs.

Rapid Model Experimentation

Researchers deploy the lightweight CLI to quickly iterate on experimental fine-tuning runs without renting expensive cloud clusters.

Memory Constrained Training

Machine learning engineers leverage the layer streaming architecture to train models that would normally exceed their available VRAM.

High-Speed Execution

Developers frustrated with the overhead of Python frameworks utilize the C++ core for maximum raw training throughput.

Getting started: git clone https://github.com/MakazhanAlpamys/Soup.git

README

main branch

🌍 English | Türkçe | العربية | 日本語 | 中文

Soup

Soup

Fine-tune and post-train LLMs in one command. No SSH, no config hell.

Website · Quick Start · Web UI · Config · Docs · Commands · Models · Discord · Telegram · Product Hunt

PyPI Downloads Python 3.10-3.12 Apache-2.0 License Tests CI Website Discord Telegram DOI: 10.5281/zenodo.21771064

Soup CLI - Fine-tune an 8B LLM on a 4 GB laptop GPU | Product Hunt MakazhanAlpamys/Soup | Trendshift


Soup turns the pain of LLM fine-tuning into a simple workflow. One config, one command, done.

pip install "soup-cli[train]"   # add [train] to fine-tune; bare `soup-cli` is the light CLI
soup init --template chat
soup train

Fine-tune an 8B model on a 4 GB laptop GPU. Layer streaming keeps the frozen base out of VRAM and feeds it to the GPU one decoder layer at a time. Measured on an RTX 3050 Laptop 4 GB: Llama-3.1-8B-Instruct + NF4 at 119.6 tok/s at 952 MHz, 3.32 GB peak (pre-repair) — bit-exact against a normal resident run, and reproduced independently on an H100 at 113.00 tok/s in the same 3.32 GB. (Both figures were measured on v0.72.2, before the v0.73.0 correctness repair that cost −4.8% at 32B. The post-repair run, on another RTX 3050 Laptop 4 GB (@umran666, #1103), reads 208.6 tok/s at 1935–1957 MHz in a 2.40 GB peak. That is 59% of its same-session GEMM ceiling against 68%: about 14% slower per unit clock, so the raw 1.74x gain is the clock, not a speedup. Large-layer streaming also changed the memory pattern between the two rows, so even the fraction is not like-for-like — the record.) Opt-in (stream_layers: true) and still BETA — how it works · all measurements · paper · check it yourself on a free Colab T4 (caps the process to 4 GB, then asserts a streamed model is bit-identical to a normal one)
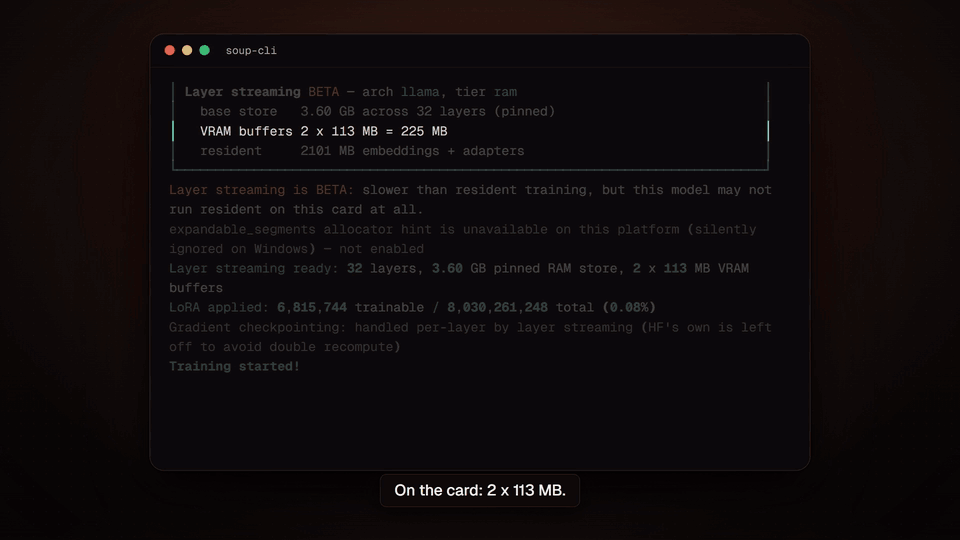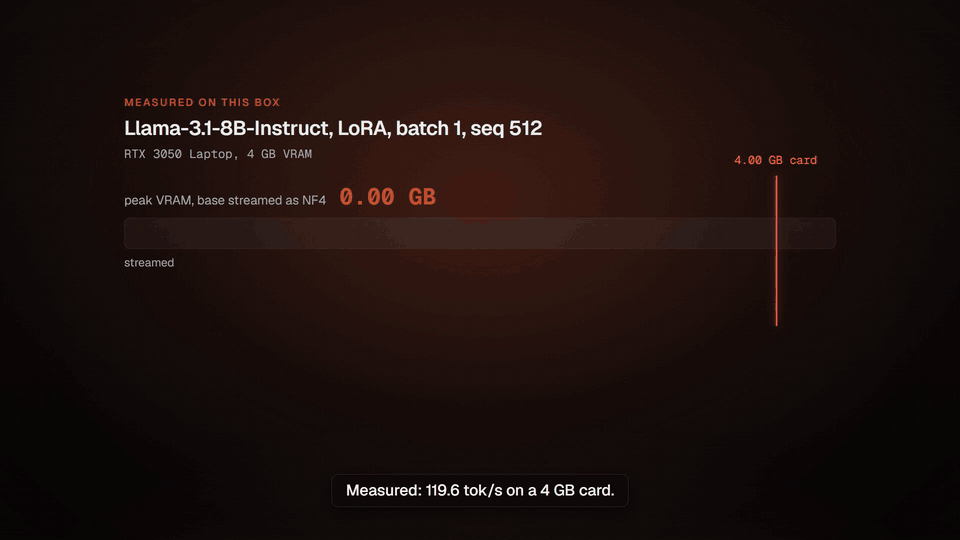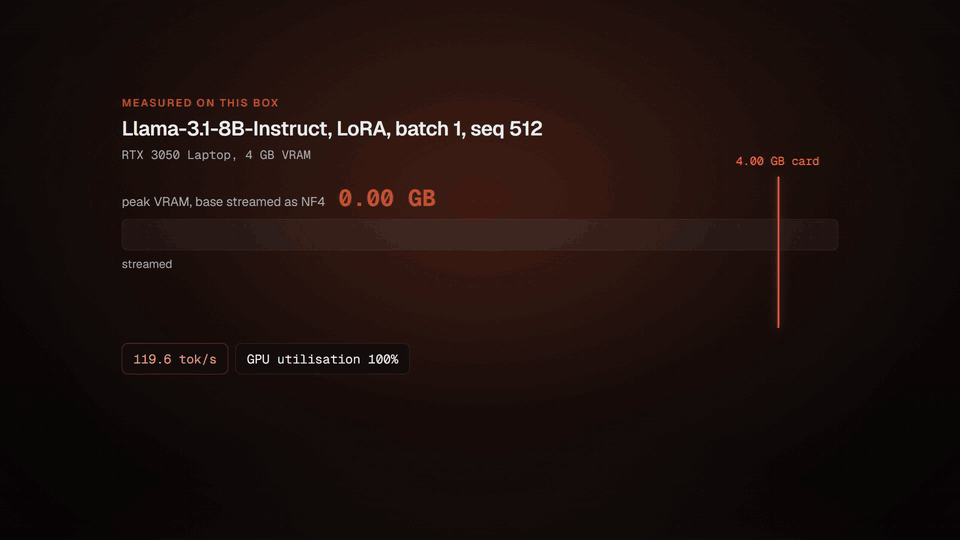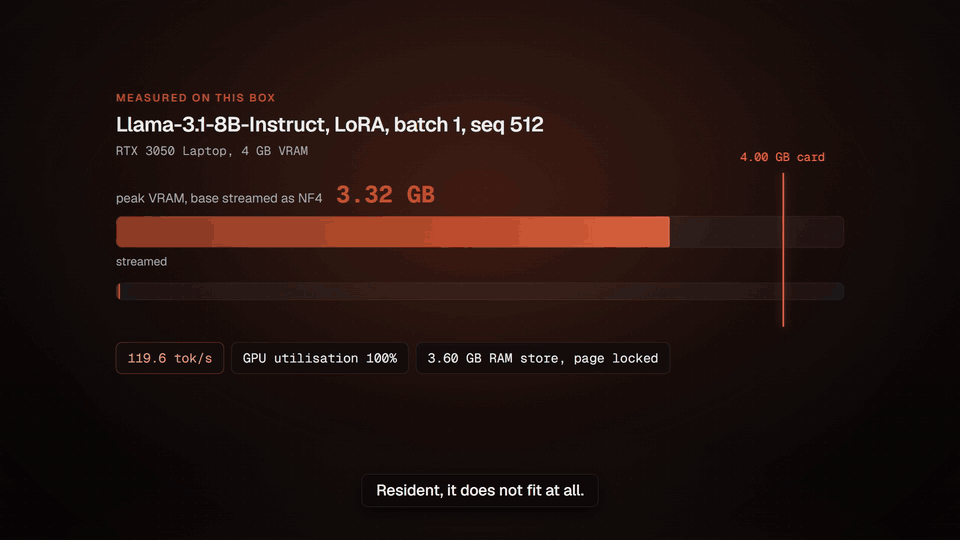
soup train pre-flight for Llama-3.1-8B on a 4 GB card: a 3.60 GB base store pinned in RAM across 32 layers and two 113 MB VRAM buffers, then a measured peak of 3.32 GB at 119.6 tok/s, stopping short of the 4 GB line (pre-repair row, measured on v0.72.2 at 952 MHz; the post-#331 row is in the caption below)
Llama-3.1-8B-Instruct + NF4, LoRA, batch 1, seq 512 on an RTX 3050 Laptop 4 GB — 3.32 GB peak, 119.6 tok/s at 952 MHz (pre-repair, v0.72.2; post-#331: 208.6 tok/s at 1935 MHz in 2.40 GB, not directly comparable, @umran666, #1103). Full video (90s)

Why Soup?

Training LLMs is still painful. Even experienced teams spend 30-50% of their time fighting infrastructure instead of improving models. Soup fixes that.

  • Zero SSH. Never SSH into a broken GPU box again.
  • One config. A simple YAML file is all you need.
  • Auto everything. Batch size, GPU detection, quantization — handled.
  • Works locally. Train on your own GPU with QLoRA. No cloud required.

What's New

v0.76.0 — settings Soup accepted and never applied now stop the load. Options that were validated and documented, and read by nothing on the path they claimed to configure, are now refused at load, naming the setting and what to change; the rest warn and name the release that will refuse them. A config that loaded before can stop loading: run soup doctor --config soup.yaml first.

  • Breaking: a setting that never took effect is refused at load. Among them training.quantization_aware: true (it never ran quantization-aware training), training.use_longlora, training.ebft_variant, training.gdpo_variant, training.rope_scaling_type where no setup reads it, freeze_layers / freeze_ratio outside the text sft / tts path on the transformers backend, auto_mixed_precision outside sft / tts, and backend: unsloth on seven further tasks that have no unsloth setup. Each message names the field and what to change. lr_groups, early_stop_patience, forgetting_eval_steps and other unread knobs warn at load now and are refused from v0.77.
  • Validation loss is now evaluated. data.val_split held rows out of training on every run, and no trainer on the transformers backend evaluated them. Every task that gets a split now evaluates it at the end of each epoch, or every N steps with training.eval_steps, and records the val loss; runs take a few percent longer. Breaking for grpo, ppo and online_dpo: by default they no longer hold rows out (data.val_split is ignored with a note), so every row trains.
  • Breaking: every non-standard grpo_variant applies the grpo_beta KL penalty. gspo, dapo, dr_grpo, bnpo, two_sided and rft validated grpo_beta and dropped it, so existing variant configs will not reproduce prior runs. grpo_beta: 0 now runs KL-free and skips the reference forward pass.
  • Layer streaming reads its disk tier on a background thread, through direct I/O, and can stripe it across NVMe drives. On a 36 GB 70B-shaped NF4 store larger than RAM (one RTX 5070 Laptop 8 GB box), a cold step went from 110.5 s on the synchronous read to 16.2-17.3 s, and from 17.4 s to 9.97 s across two drives with SOUP_LAYER_STREAM_STRIPE_DIRS (a sustained-load probe: two rounds, 1.28x and 1.41x, no formal verdict; record). A store that fits RAM is still faster on the RAM tier, which stream_source: auto picks. Opt-in (stream_layers: true) and still BETA; records: direct I/O, striping.
  • New commands and options. soup adapters check scans a LoRA adapter for silent failure; soup bench train trains a fixed number of steps and exits 1 when the model was not training (it covers task: sft on the transformers backend; soup bench is now a group, and soup bench infer is the old inference benchmark); soup data clean sanitizes and repairs a dataset without touching the input file; soup recipes verify checks on the meta device, with no weights downloaded, that every shipped recipe can attach a LoRA adapter; soup rewind names the dataset rows behind a loss spike. soup infer gains opt-in --batch-size and an experimental --cuda-graphs (PyTorch 2.14 or newer; on one RTX 5070 Laptop, unpinned, Qwen2.5-1.5B in FP16, the slowest run with it decoded 2.9x faster than the fastest without). soup ab runs a two-sided, variance-robust test, and soup adapters sign --backend sigstore and soup attest emit --sign sigstore sign with Sigstore keyless OIDC (pip install "soup-cli[sigstore]").
  • Deprecated: soup export --format awq and --format gptq will be removed in v0.77; both upstream projects are archived and neither extra installs next to [train].

Python 3.10–3.12 only. On 3.13+, pip used to resolve untested PyTorch wheels that crash in the native extension before Soup runs at all.

Older highlights live on the GitHub Releases page.

Quick Start

1. Install

Soup is a command-line application, so the cleanest install gives it its own environment and puts soup on your PATH:

# Light core: CLI + config + data tools, no PyTorch
pipx install soup-cli
uv tool install soup-cli          # same idea, if you already use uv

# Add the training stack (torch, transformers, peft, trl, datasets, …)
pipx install "soup-cli[train]"

# Everything (train + serve + ui + data) in one shot
pipx install "soup-cli[all]"

# Or from GitHub (latest dev)
pipx install "git+https://github.com/MakazhanAlpamys/Soup.git"

Already inside a virtualenv, a Colab notebook, or a Docker image? Use pip directly, with the same names and extras:

pip install soup-cli
pip install "soup-cli[train]"
pip install "soup-cli[all]"
pip install git+https://github.com/MakazhanAlpamys/Soup.git

Use pip rather than pipx if you also want to import soup_cli from your own code, since pipx deliberately isolates the application from everything else.

The full extras table (fast, mlx, serve, eval, ui, vision, audio, …) lives in docs/models.md.

error: externally-managed-environment? That is PEP 668, not a Soup problem. Debian 12, Ubuntu 23.04 and later stop pip from writing into the system Python, because apt manages those files too. pipx and uv tool sidestep it by giving Soup its own environment, which is why they are listed first above. python3 -m venv .venv && source .venv/bin/activate then plain pip works just as well.

Double quotes, not single. "soup-cli[train]" is the only spelling that works in every shell — cmd.exe, PowerShell, bash and zsh. If you copied 'soup-cli[train]' from an older tutorial and pip rejected it, that is the reason: why, and the exact error.

soup init, soup data …, and the other data/inspection commands work on the light install. Fine-tuning (soup train) needs the [train] extra.

2. Create a config

soup init                       # interactive wizard
soup init --template chat       # or start from a template

Templates: chat, code, tool-calling, medical, reasoning, vision, kto, orpo, simpo, ipo, bco, rlhf, pretrain, moe, longcontext, embedding, audio.

3. Train, test, ship

soup train --config soup.yaml                 # LoRA, quantization, batching — all handled
soup chat  --model ./output                    # talk to your model
soup push  --model ./output --repo you/my-model

soup merge  --adapter ./output                              # merge LoRA into the base
soup export --model ./output --format gguf --quant q4_k_m   # GGUF for Ollama / llama.cpp

More export targets (ONNX, TensorRT, AWQ, GPTQ, BitNet) and deployment options live in docs/serving-and-export.md.

Web UI

Prefer a browser? soup ui serves a local dashboard for experiments, training setup, live metrics, dataset exploration and model chat.

pip install "soup-cli[ui]"
soup ui
# Opens http://127.0.0.1:7860/?token=<token> and prints the same URL

Soup Web UI — New Training

Web UI documentation

Configuration

A complete soup.yaml:

base: meta-llama/Llama-3.1-8B-Instruct
task: sft
# backend: unsloth  # 2-5x faster, pip install "soup-cli[fast]"

data:
  train: ./data/train.jsonl
  format: alpaca
  val_split: 0.1

training:
  epochs: 3
  lr: 2e-5
  batch_size: auto
  lora:
    r: 64
    alpha: 16
  quantization: 4bit

output: ./output

config/schema.py is the single source of truth for every field. Advanced data, training, and PEFT options are documented under Documentation.

Unknown config keys are rejected since v0.75. A key no model declares — a typo like quantizaton, or a field that only exists on a newer Soup — used to validate clean and be discarded, so the run proceeded with the setting simply not applied. v0.74 reported it at load with the field you probably meant; from v0.75 the same config fails to load, so fix or remove the key rather than relying on it being ignored. See Unknown config keys.

Documentation

The full feature reference lives in docs/. Start here:

Guide Covers
Training tasks & methods SFT, DPO/GRPO/PPO/KTO/ORPO/SimPO/IPO/BCO, tool-calling, PRM, pre-training, distillation, classification, vision/audio/TTS, unlearning, RAFT/RA-DIT, loop-hardening detectors
PEFT, long context & efficiency DoRA, LoRA+, rsLoRA, VeRA, OLoRA, NEFTune, PiSSA, ReLoRA, optimizer & PEFT zoo, LLaMA Pro, GaLore, YaRN/LongLoRA, packing, curriculum, auto-tuning
Performance & quantization QAT, FP8, Quant Menu (I + II), KV-cache, NVFP4, save formats, Cut Cross-Entropy, gradient checkpointing, kernels, activation offloading, layer streaming, multi-GPU / DeepSpeed / FSDP
Data engineering Formats, the Axolotl/LF-parity pipeline, data tools, synthetic generation & forge, quality scorecards, trace tooling, remote datasets, mixing, recipe DAGs
Evaluation & probes Eval design/gate, eval-gated training, benchmarks, NLG metrics, calibration, Elo arena, diagnose, post-train X-ray probes, A/B, drift, tunability, soup advise
Serving & export OpenAI-compatible server, batch inference, benchmarking, merge/export, Anthropic Messages endpoint, speculative decoding (train + measure your own draft), deploy autopilot, Web UI, Agent Forge
Adapters, registry & governance Adapter lifecycle/management, model registry, Soup Cans, the data flywheel (soup loop), knowledge editing, steering, supply-chain controls (scan/sign/BOM/attest/audit/airgap)
Compliance & governance quickstart HIPAA/SOC2/EU-AI-Act/SR-11-7 init templates, provenance (BOM/attest/repro-receipt), audit log, air-gap, model-card autogen (soup card), CI gate (soup ci init)
Backends, platform & ops MLX/Unsloth backends, alternative hubs, HF Hub integration, autopilot, experiment tracking, plan/apply, env lockfiles, hardware-fit, completions, plugins, utility commands
Command reference The full soup command list
Supported models & extras Recommended model families, the VRAM size guide, the pip extras matrix

Data Formats

Alpaca, ShareGPT, ChatML, preference pairs (DPO / ORPO / SimPO / IPO / KTO), vision, audio, ASR, plaintext, embedding, RAFT and more — all auto-detected from JSONL, JSON, CSV, Parquet or TXT, so in most cases you point data.train at a file and nothing else changes. Schemas with a worked example per format, plus the data pipeline (remote URIs, streaming, sharding, interleaving, vocab expansion, document ingestion), are in docs/data.md.

Common Commands

soup train  --config soup.yaml        # train (SFT/DPO/GRPO/PPO/KTO/ORPO/SimPO/IPO/...)
soup infer  --model ./output --input prompts.jsonl --output results.jsonl   # batch inference
soup chat   --model ./output          # interactive chat
soup serve  --model ./output          # OpenAI-compatible API server
soup ui                               # local browser dashboard
soup merge  --adapter ./output        # merge LoRA into the base model
soup export --model ./output --format gguf           # export for deployment
soup eval   benchmark --model ./output               # evaluate
soup data   inspect ./data/train.jsonl               # dataset stats
soup recipes list                     # 100+ ready-made model recipes
soup autopilot --model <id> --data d.jsonl --goal chat  # zero-config
soup doctor                           # check GPU / deps / environment

The complete command list is in docs/commands.md.

Supported Models

Soup works with any text-generation model on the HuggingFace Hub — if it loads with AutoModelForCausalLM, it works, zero config changes. Llama 3.x/4, Qwen 2.5/3, Gemma 3, Mistral, Mixtral, DeepSeek R1/V3, Phi-4, and 100+ others ship as ready-made recipes (soup recipes list).

VRAM Max model (QLoRA 4-bit) Example
8 GB ~7B Llama-3.1-8B, Mistral-7B
16 GB ~14B Phi-4-14B, Qwen2.5-14B
24 GB ~34B CodeLlama-34B, Yi-1.5-34B
48 GB ~70B Llama-3.3-70B
80 GB+ 70B+ (full) or MoE Mixtral-8x22B, DeepSeek-V3

Full model + vision tables and the optional-extras matrix are in docs/models.md.

Docker

Run Soup without installing CUDA or PyTorch locally (image published to GHCR on every release):

docker pull ghcr.io/makazhanalpamys/soup:latest
docker run --gpus all -v $(pwd):/workspace ghcr.io/makazhanalpamys/soup train --config soup.yaml
docker compose up   # or build locally

Requirements

  • Python 3.10, 3.11 or 3.12 (those are the versions CI tests; 3.13+ is not supported yet because the PyTorch stack has not been validated there)
  • GPU with CUDA (recommended), Apple Silicon (MPS), or CPU (experimental — very slow)
  • 8 GB+ VRAM for 7B models with QLoRA

All training tasks run on CPU for testing (quantization auto-disabled). Optional extras (train, all, fast, vision, qat, serve, serve-fast, ui, eval, deepspeed, liger, mlx, onnx, tensorrt, …) are listed in docs/models.md.

Troubleshooting

soup doctor    # GPU, system resources, dependencies, and version in one place

CUDA wheels, version mismatches: docs/backends-and-ops.md.

Development

git clone https://github.com/MakazhanAlpamys/Soup.git
cd Soup
pip install -e ".[dev]"

ruff check src/soup_cli/ tests/    # lint
pytest tests/ -v                   # unit tests (fast, no GPU)
pytest tests/ -m smoke -v          # smoke tests (downloads a tiny model, trains)
pytest tests/ -m gpu --no-cov -v   # GPU tests (need a CUDA card; report results, see CONTRIBUTING.md)

pre-commit install                 # optional: ruff lint+format on commit

See CONTRIBUTING.md for the full workflow and SECURITY.md to report a vulnerability. Telemetry is strictly opt-in (SOUP_TELEMETRY=1, default off; see Privacy Policy).

Support Soup

Soup is Apache-2.0 and free — and stays that way. It is built and maintained in the open on a single 4 GB laptop, which is why every performance number in these docs is measured rather than claimed.

If Soup saved you a training run, starring the repo helps most, and it costs nothing. If you would like to fund the work directly:

❤️ Donate — one-off, any amount (use Change amount on the checkout page). Payments are processed by Stripe under the maintainer's registered business, MePlay, Inc. — that name, not "Soup", is what appears on the checkout page and on your card statement.

Donations buy GPU time for the hardware-gated work — multi-GPU, 8B+ validation, Apple Silicon — that a single 4 GB laptop cannot reach.

The other way to move exactly those items is hardware itself. They ship behind honest "requires <hardware>" gates rather than unverified claims, so if you have access to a bigger box — or GPU credits going unused — running one of the help wanted issues and posting the numbers helps as much as funding the GPU time would. Those issues say exactly what is blocked on hardware today.

Contributors

Built by the community ❤️ — thank you to everyone who has contributed. See CONTRIBUTORS.md.

Contributors

Contact

Bugs and feature requests belong in the issue tracker, questions in Discussions — both get answered faster and help the next person with the same problem.

For live chat, setup help, and everything that reads better as a conversation, join the Discord or the Telegram community. Anything that should still be findable in six months belongs in Issues or Discussions — a Discord answer helps one person, an issue helps everyone who hits the same thing. The Code of Conduct applies there too.

For anything that does not fit in public — security reports (see SECURITY.md), Code of Conduct matters, or press — email [email protected]. That is the project address and the right one for anything Soup-related. [email protected] is the maintainer's personal address; it reaches the same person and is a fine fallback.

Citing Soup

Layer streaming — training an 8B model on a 4 GB laptop GPU by streaming the frozen base from host RAM one decoder layer at a time — is described in a preprint, together with the correctness protocol that verifies a streamed run against a resident one (forward and backward stated separately, because they are two claims and not one).

Makazhan, A. (2026). Exact Layer Streaming: LoRA Fine-Tuning of an 8B Model on a 4 GB Laptop GPU (v3). Zenodo. https://doi.org/10.5281/zenodo.21918325

Version 3 (13 August 2026) is current. The title and the claim are unchanged — 8B on 4 GB — and no measured number has changed since v1. What v3 does is withdraw an explanation we had published, which is also the shortest way to describe what the paper is for:

  • Retracted in v3: "layer streaming is bound by host-to-device transfer, not by the GPU." That was an inference from the H100 replication below, and it had never been measured. We measured it on 11 August and it is false at the published configuration: deleting every host-to-device byte buys 1.4%, the compute stream waits on a copy for 0.20% of the step, and the step runs at 71.3% of that card's same-session GEMM ceiling. The largest streaming-specific cost is the per-layer NF4 dequantisation, at 9.8% (the record). Every measurement stands; the replication survives in a weaker form — the constraint is common to both machines and is not the GPU's compute.
  • Replication on hardware nothing like the original (added in v2): 119.6 tok/s on the RTX 3050 (at 952 MHz) against a median 113.00 on an H100, at the same 3.32 GB peak. Both pre-date the #331 repair and are the figures the paper reports. The post-#331 row (@umran666, #1103) is 208.6 tok/s at 1935–1957 MHz in a 2.40 GB peak, 59% against 68% of the same-session GEMM ceiling: the raw 1.74x gain is the clock, not a speedup, and the memory pattern changed between the rows, so even the fraction is not like-for-like (the record).
  • A silent wrong-gradient defect, found and repaired. On NF4 above ~165 MiB per layer the forward stayed bit-exact and the loss curve looked healthy while the gradients were wrong. The cause is named in the upstream library and reported there; the repair is gated against controls on real 32B and 72B.
  • Bit-exactness at real model sizes instead of three-layer toys: forward from 0.5B to 72B, backward at 8B and 14B.
  • Trained-model quality, measured for the first time, and indistinguishable from a resident run.
  • A comparison against DeepSpeed — including the result that does not flatter us: eight cards of ZeRO-3 are slower than one card training resident.
  • The limitations section rewritten: of v1's ten items, one closed and four more narrowed, and seven new ones added.

Cite the version you used. 10.5281/zenodo.21771064 is the concept DOI and always resolves to the latest version (v3 today); v1 and v2 remain citable at their own version DOIs and are not edited — the retraction above is a new version precisely so that the record of what we claimed, and when, stays intact.

The measurement records behind every number in it are in benchmarks/, published as written — including the failures, the assumptions that turned out wrong, and the numbers that were measured and then discarded.

@misc{makazhan2026exact,
  title        = {Exact Layer Streaming: LoRA Fine-Tuning of an 8B Model on a 4 GB Laptop GPU},
  author       = {Makazhan, Alpamys},
  year         = {2026},
  publisher    = {Zenodo},
  version      = {v3},
  doi          = {10.5281/zenodo.21918325},
  url          = {https://doi.org/10.5281/zenodo.21918325}
}

License

Apache-2.0. Copyright 2026 Makazhan Alpamys and the Soup contributors. If you redistribute Soup or a modified copy of it, sections 4 and 6 of the license apply to you: keep LICENSE and NOTICE with every copy, mark the files you changed, and do not use the Soup name beyond saying where the work comes from.

View on GitHub

Recent activity

commits and pull requests

Recent open issues

view all

Discussions

all 7

Releases and announcements

181 total
  1. Soup CLI v0.76.1v0.76.1Oct 14, 2026

    ## Soup CLI v0.76.1 A patch release on the v0.76.0 line. It makes the bundled DPO examples train again, puts the same nesting and expansion limits, and a size cap, on every YAML file Soup reads, fixes the declared Typer floor, and loads Hub dataset ids that contain a dot. Everything in v0.76.0 is unchanged. ## Highlights - The bundled DPO examples train again: `task: dpo`, `ipo`, `bco` and `preference` no longer fail inside trl on `examples/data/dpo_sample.jsonl`, `examples/data/chat_preferences.jsonl` or any dataset written the same way (#1849, #1866). - `soup.yaml` and every other YAML file Soup reads go through one loader with the same nesting and expansion limits, and a per-reader size cap (#1827). - The Typer floor is now `typer>=0.15.4`, and a CI cell starts the CLI on the declared Typer and Click floors (#1802, #1858). - A single-string `data.train` that names a Hub dataset with a dot in its name, such as `teknium/OpenHermes-2.5`, loads from the Hub (#1889). - The README and the performance docs state the 8B NF4 figure with its SM clock and give the post-#331 row (#1207, #1699). ## Fixed - **DPO-family tasks on the bundled examples (#1849, #1866).** A string `prompt` be

  2. 490 pull requests have merged since 2026-09-12, the day v0.75.0 shipped, and **418 of them came from 80 people outside the maintainer.** What they found is the release: settings that Soup validated, documented and accepted, and then read nowhere on the path they claimed to configure, so a `soup.yaml` could ask for one thing and quietly train another. This release refuses the settings that never took effect, warns about the rest and names the release that will refuse them, evaluates the validation split Soup always held out and never used, and applies the `grpo_beta` KL penalty to every GRPO variant. It also adds `soup adapters check`, `soup bench train`, `soup data clean`, `soup recipes verify` and `soup rewind`, and the layer-streaming disk tier now reads on a background thread, through direct I/O, and can stripe across NVMe drives. **A config that loaded on v0.75 can stop loading: run `soup doctor --config soup.yaml` before you train.** ## What's New ### Breaking changes (read these first) - **A setting that never took effect is refused at load.** Each message names the field and what to change. Among them: `training.quantization_aware: true` (#1222; it never ran quantization-

  3. A security patch release for the 0.75 line. It carries one hardening change and nothing else; everything merged on `main` since 0.75.0 ships in the next minor release. ## What's New - **Outbound endpoint checks refuse private IP literals on every scheme.** `soup data generate --api-base`, the vLLM provider and the commands that use it, judge URLs in `soup eval judge`, eval-gate suites, `soup ship --judge-model` / `eval.ship.judge_model`, `training.online_dpo_judge`, and the Web UI chat proxy now refuse a private, link-local or reserved IP literal over `https` as well as `http`. Loopback still works; address a server on your network by its hostname. `training.online_dpo_judge` is checked when soup.yaml loads, not only when the trainer starts. - **`http://0.0.0.0` is no longer treated as local** by `soup data generate --api-base` and the Web UI chat proxy; use `localhost` or `127.0.0.1`. - **`100.64.0.0/10` and `fec0::/10` are non-public** for every check that already refused private addresses (webhooks, the OTLP endpoint, telemetry, hub endpoints over HTTP, and `soup ingest --pull`, where `--allow-private-host` admits them). - **Non-ASCII spellings of an address are classified as

  4. **v0.75.1 is a backport, not a cut of `main`.** Its tree is tag `v0.75.0` plus 25 cherry-picks, one test adaptation and the release commits. `main` was 186 commits past `v0.75.0` when this release was cut, so releasing from `main` would have shipped an entire minor's worth of unreleased work under a patch number. The diff of `v0.75.0...v0.75.1` is exactly what these notes describe. ## What's New - **A layer-streamed LoRA adapter saved as ZERO tensors under peft 0.21.0** (#1005, fixed in #1010). peft 0.21 selects an adapter's tensors by the prefixes it reads off `model.named_modules()`, where 0.20 filtered by the `lora_` substring. The streaming wrapper's module and parameter names carried `.inner.` while its `state_dict()` keys were canonical, so `trainer.save_model()`, every `save_steps` checkpoint and `get_peft_model_state_dict()` returned nothing — and nothing raised. **Any adapter saved with `stream_layers: true` on peft>=0.21 before this fix holds zero tensors (a 40-byte `adapter_model.safetensors`) and cannot be recovered: re-train it.** Naming only; nothing on the streamed forward path changes. - **`soup runs clean --keep-weights` did the opp

  5. **All 60 pull requests in this release came from outside the maintainer**, by 22 people. What they found is the release: on the MLX backend, six training options were validated, documented, accepted — and read by nothing, so the same `soup.yaml` trained a different recipe on Apple Silicon than on a CUDA box, silently. And the deadline v0.74.0 promised is honoured: an unknown config key now refuses the load. ## What's New - **Breaking: an unknown config key refuses the load.** v0.74.0 reported every key no config model declares — a typo like `quantizaton`, or a field that only exists on a newer Soup — as a warning that named v0.75 as the release that would start refusing. This is that release: `soup train` exits 1 before the training stack is imported, and the API / Web UI loader raises `ValueError` with the same text, naming the field you probably meant. Nothing is defaulted or substituted. The refusal says `Refused.` rather than `Not applied.`; the `soup sweep` guard, which always refused, changes wording the same way. The detector sees a config the way `SoupConfig` does: a root-level `lora:` block (the LlamaFactory / Axolotl spelling the schema has accepted and moved under `tra

Code frequency

additions and deletions
+154.4K-154.4KWeek of 2026-02-15: +2,003 linesWeek of 2026-02-15: -33 linesWeek of 2026-02-22: +3,111 linesWeek of 2026-02-22: -67 linesWeek of 2026-03-01: +6,394 linesWeek of 2026-03-01: -295 linesWeek of 2026-03-08: +0 linesWeek of 2026-03-08: -0 linesWeek of 2026-03-15: +0 linesWeek of 2026-03-15: -0 linesWeek of 2026-03-22: +28,037 linesWeek of 2026-03-22: -2,078 linesWeek of 2026-03-29: +17,744 linesWeek of 2026-03-29: -492 linesWeek of 2026-04-05: +3,027 linesWeek of 2026-04-05: -220 linesWeek of 2026-04-12: +5,716 linesWeek of 2026-04-12: -83 linesWeek of 2026-04-19: +16,951 linesWeek of 2026-04-19: -1,069 linesWeek of 2026-04-26: +21,176 linesWeek of 2026-04-26: -590 linesWeek of 2026-05-03: +6,917 linesWeek of 2026-05-03: -662 linesWeek of 2026-05-10: +71,672 linesWeek of 2026-05-10: -1,224 linesWeek of 2026-05-17: +37,223 linesWeek of 2026-05-17: -273 linesWeek of 2026-05-24: +21,230 linesWeek of 2026-05-24: -183 linesWeek of 2026-05-31: +154,401 linesWeek of 2026-05-31: -116,255 linesWeek of 2026-06-07: +17,995 linesWeek of 2026-06-07: -824 linesWeek of 2026-06-14: +112 linesWeek of 2026-06-14: -10 linesWeek of 2026-06-21: +3,179 linesWeek of 2026-06-21: -49 linesWeek of 2026-06-28: +14,328 linesWeek of 2026-06-28: -530 linesWeek of 2026-07-05: +12,267 linesWeek of 2026-07-05: -2,143 linesWeek of 2026-07-12: +15,015 linesWeek of 2026-07-12: -867 linesWeek of 2026-07-19: +5,946 linesWeek of 2026-07-19: -161 linesWeek of 2026-07-26: +11,707 linesWeek of 2026-07-26: -417 linesWeek of 2026-08-02: +15,488 linesWeek of 2026-08-02: -1,914 linesWeek of 2026-08-09: +14,582 linesWeek of 2026-08-09: -1,534 linesWeek of 2026-08-16: +17,666 linesWeek of 2026-08-16: -1,376 linesWeek of 2026-08-23: +20,573 linesWeek of 2026-08-23: -1,380 linesWeek of 2026-08-30: +76,637 linesWeek of 2026-08-30: -51,637 linesWeek of 2026-09-06: +22,822 linesWeek of 2026-09-06: -1,570 linesWeek of 2026-09-13: +123,637 linesWeek of 2026-09-13: -4,403 linesWeek of 2026-09-20: +47,515 linesWeek of 2026-09-20: -3,039 linesWeek of 2026-09-27: +101,477 linesWeek of 2026-09-27: -5,418 linesWeek of 2026-10-04: +0 linesWeek of 2026-10-04: -0 linesFeb 15, 2026Oct 4, 2026
+916.5K lines added, -200.8K removed over the last year.

Commits per week

last 52 weeks
1830Week of 2025-10-18: 0 commitsWeek of 2025-10-25: 0 commitsWeek of 2025-11-01: 0 commitsWeek of 2025-11-09: 0 commitsWeek of 2025-11-16: 0 commitsWeek of 2025-11-23: 0 commitsWeek of 2025-11-30: 0 commitsWeek of 2025-12-07: 0 commitsWeek of 2025-12-14: 0 commitsWeek of 2025-12-21: 0 commitsWeek of 2025-12-28: 0 commitsWeek of 2026-01-04: 0 commitsWeek of 2026-01-11: 0 commitsWeek of 2026-01-18: 0 commitsWeek of 2026-01-25: 0 commitsWeek of 2026-02-01: 0 commitsWeek of 2026-02-08: 0 commitsWeek of 2026-02-15: 5 commitsWeek of 2026-02-22: 4 commitsWeek of 2026-03-01: 20 commitsWeek of 2026-03-08: 0 commitsWeek of 2026-03-15: 0 commitsWeek of 2026-03-22: 95 commitsWeek of 2026-03-29: 40 commitsWeek of 2026-04-05: 11 commitsWeek of 2026-04-12: 7 commitsWeek of 2026-04-19: 23 commitsWeek of 2026-04-26: 27 commitsWeek of 2026-05-03: 18 commitsWeek of 2026-05-10: 54 commitsWeek of 2026-05-17: 20 commitsWeek of 2026-05-24: 13 commitsWeek of 2026-05-31: 44 commitsWeek of 2026-06-07: 18 commitsWeek of 2026-06-14: 3 commitsWeek of 2026-06-21: 5 commitsWeek of 2026-06-28: 36 commitsWeek of 2026-07-05: 65 commitsWeek of 2026-07-12: 56 commitsWeek of 2026-07-19: 8 commitsWeek of 2026-07-26: 20 commitsWeek of 2026-08-02: 111 commitsWeek of 2026-08-09: 78 commitsWeek of 2026-08-16: 95 commitsWeek of 2026-08-23: 101 commitsWeek of 2026-08-30: 113 commitsWeek of 2026-09-06: 101 commitsWeek of 2026-09-13: 183 commitsWeek of 2026-09-20: 100 commitsWeek of 2026-09-27: 158 commitsWeek of 2026-10-04: 159 commitsWeek of 2026-10-11: 100 commitsOct 18, 2025Oct 11, 2026
1.9K commits in the last 52 weeks.

When work happens

weekday and hour
SunMonTueWedThuFriSat036912151821Sun 0:00 — 3 commitsSun 1:00 — 0 commitsSun 2:00 — 1 commitsSun 3:00 — 2 commitsSun 4:00 — 2 commitsSun 5:00 — 1 commitsSun 6:00 — 3 commitsSun 7:00 — 0 commitsSun 8:00 — 2 commitsSun 9:00 — 3 commitsSun 10:00 — 11 commitsSun 11:00 — 8 commitsSun 12:00 — 11 commitsSun 13:00 — 19 commitsSun 14:00 — 20 commitsSun 15:00 — 27 commitsSun 16:00 — 30 commitsSun 17:00 — 22 commitsSun 18:00 — 9 commitsSun 19:00 — 22 commitsSun 20:00 — 18 commitsSun 21:00 — 22 commitsSun 22:00 — 10 commitsSun 23:00 — 5 commitsMon 0:00 — 4 commitsMon 1:00 — 3 commitsMon 2:00 — 0 commitsMon 3:00 — 0 commitsMon 4:00 — 1 commitsMon 5:00 — 4 commitsMon 6:00 — 1 commitsMon 7:00 — 4 commitsMon 8:00 — 9 commitsMon 9:00 — 8 commitsMon 10:00 — 12 commitsMon 11:00 — 11 commitsMon 12:00 — 13 commitsMon 13:00 — 20 commitsMon 14:00 — 12 commitsMon 15:00 — 10 commitsMon 16:00 — 24 commitsMon 17:00 — 14 commitsMon 18:00 — 23 commitsMon 19:00 — 29 commitsMon 20:00 — 42 commitsMon 21:00 — 38 commitsMon 22:00 — 30 commitsMon 23:00 — 26 commitsTue 0:00 — 9 commitsTue 1:00 — 3 commitsTue 2:00 — 2 commitsTue 3:00 — 0 commitsTue 4:00 — 1 commitsTue 5:00 — 0 commitsTue 6:00 — 1 commitsTue 7:00 — 2 commitsTue 8:00 — 6 commitsTue 9:00 — 5 commitsTue 10:00 — 4 commitsTue 11:00 — 16 commitsTue 12:00 — 35 commitsTue 13:00 — 20 commitsTue 14:00 — 13 commitsTue 15:00 — 23 commitsTue 16:00 — 15 commitsTue 17:00 — 14 commitsTue 18:00 — 15 commitsTue 19:00 — 14 commitsTue 20:00 — 8 commitsTue 21:00 — 10 commitsTue 22:00 — 19 commitsTue 23:00 — 15 commitsWed 0:00 — 21 commitsWed 1:00 — 5 commitsWed 2:00 — 11 commitsWed 3:00 — 2 commitsWed 4:00 — 1 commitsWed 5:00 — 1 commitsWed 6:00 — 1 commitsWed 7:00 — 3 commitsWed 8:00 — 1 commitsWed 9:00 — 3 commitsWed 10:00 — 4 commitsWed 11:00 — 4 commitsWed 12:00 — 23 commitsWed 13:00 — 25 commitsWed 14:00 — 17 commitsWed 15:00 — 27 commitsWed 16:00 — 20 commitsWed 17:00 — 21 commitsWed 18:00 — 31 commitsWed 19:00 — 13 commitsWed 20:00 — 13 commitsWed 21:00 — 17 commitsWed 22:00 — 16 commitsWed 23:00 — 20 commitsThu 0:00 — 16 commitsThu 1:00 — 6 commitsThu 2:00 — 3 commitsThu 3:00 — 4 commitsThu 4:00 — 3 commitsThu 5:00 — 1 commitsThu 6:00 — 1 commitsThu 7:00 — 3 commitsThu 8:00 — 1 commitsThu 9:00 — 1 commitsThu 10:00 — 10 commitsThu 11:00 — 6 commitsThu 12:00 — 17 commitsThu 13:00 — 23 commitsThu 14:00 — 24 commitsThu 15:00 — 22 commitsThu 16:00 — 36 commitsThu 17:00 — 35 commitsThu 18:00 — 22 commitsThu 19:00 — 26 commitsThu 20:00 — 15 commitsThu 21:00 — 15 commitsThu 22:00 — 22 commitsThu 23:00 — 22 commitsFri 0:00 — 9 commitsFri 1:00 — 4 commitsFri 2:00 — 2 commitsFri 3:00 — 2 commitsFri 4:00 — 1 commitsFri 5:00 — 0 commitsFri 6:00 — 0 commitsFri 7:00 — 2 commitsFri 8:00 — 4 commitsFri 9:00 — 6 commitsFri 10:00 — 2 commitsFri 11:00 — 17 commitsFri 12:00 — 15 commitsFri 13:00 — 13 commitsFri 14:00 — 18 commitsFri 15:00 — 10 commitsFri 16:00 — 19 commitsFri 17:00 — 12 commitsFri 18:00 — 18 commitsFri 19:00 — 29 commitsFri 20:00 — 10 commitsFri 21:00 — 16 commitsFri 22:00 — 22 commitsFri 23:00 — 20 commitsSat 0:00 — 9 commitsSat 1:00 — 9 commitsSat 2:00 — 0 commitsSat 3:00 — 0 commitsSat 4:00 — 0 commitsSat 5:00 — 0 commitsSat 6:00 — 0 commitsSat 7:00 — 0 commitsSat 8:00 — 4 commitsSat 9:00 — 3 commitsSat 10:00 — 1 commitsSat 11:00 — 3 commitsSat 12:00 — 13 commitsSat 13:00 — 10 commitsSat 14:00 — 17 commitsSat 15:00 — 8 commitsSat 16:00 — 11 commitsSat 17:00 — 8 commitsSat 18:00 — 8 commitsSat 19:00 — 17 commitsSat 20:00 — 12 commitsSat 21:00 — 13 commitsSat 22:00 — 14 commitsSat 23:00 — 11 commits
Commit volume by weekday and hour (UTC). Larger dots mean more commits.

Who is committing

last 52 weeks
Maintainer commits1,184 (63%)
Community commits697 (37%)

1,881 commits in total over the last year.

DateListRankStars gained
Sep 28, 2026monthly#20+4,232
Sep 27, 2026monthly#20+4,232
Sep 26, 2026monthly#20+4,225
Sep 6, 2026weekly#15+1,808
Sep 5, 2026weekly#15+1,808
Sep 4, 2026weekly#15+1,812
Aug 17, 2026daily#6+297
Aug 16, 2026daily#6+297
  • public-apis/public-apis

    A collective list of free APIs

    492.1K stars · Python

  • morluto/rea

    Reverse engineer anything with agents, from app behavior down to native binaries.

    384.3K stars · TypeScript

  • donnemartin/system-design-primer

    Learn how to design large-scale systems. Prep for the system design interview. Includes Anki flashcards.

    375.6K stars · Python

  • affaan-m/ECC

    The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.

    288.8K stars · JavaScript

  • practical-tutorials/project-based-learning

    Curated list of project-based tutorials

    288K stars · Python

  • NousResearch/hermes-agent

    The agent that grows with you

    257K stars · Python