
huggingface/transformersPublic

🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.

AI summary: State-of-the-art Machine Learning for PyTorch, TensorFlow, and JAX.

Stars
168.2K
+62 today
Forks
35K
Watchers
1.2K
Open issues
385
Open PRs
599
Contributors
~4.2K
Commits
24.5K
Branches
1.8K

PythonApache-2.0Created Oct 29, 2018Last push todayLatest release v5.20.2+335 stars this week+1.5K this month

Quick answers

What is transformers?
State-of-the-art Machine Learning for PyTorch, TensorFlow, and JAX.
What does transformers do?
Transformers provides thousands of pretrained models to perform tasks on different modalities such as text, vision, and audio. It offers a unified API that allows researchers and engineers to easily download, train, and deploy state-of-the-art models like BERT, GPT, and ViT. The library abstracts away the complex boilerplate required for distributed training and model inference across PyTorch, TensorFlow, and JAX. It deeply integrates with the Hugging Face Hub, facilitating seamless model sharing and version control for the machine learning community. This significantly reduces the compute costs and engineering time required to implement cutting-edge AI features in production.
Who is transformers for?
Machine learning engineers, AI researchers, and software developers who need to implement state-of-the-art AI models. It requires a solid understanding of machine learning concepts and familiarity with Python deep learning frameworks.
How do I get started with transformers?
pip install transformers
How popular is transformers on GitHub?
huggingface/transformers has 168,155 stars and 34,981 forks on GitHub, and gained 335 stars in the last 7 days.
What license does transformers use?
huggingface/transformers is released under the Apache-2.0 license.

Star history

since Sep 22, 2019
050K100K150KSep 2019Jan 2022May 2024Oct 2026
168.2K stars as of Oct 25, 2026. Before Aug 12, 2026, reconstructed from public GitHub event archives (checked against the repository's real star total); since then measured daily.

Update history

3 recorded
  • Oct 23, 2026New release v5.20.2 (previously v5.20.0).
  • Oct 15, 2026New release v5.20.0 (previously v5.19.0).
  • Oct 7, 2026New release v5.19.0 (previously v5.17.0).

Contribution activity

commits per day, last 52 weeks
OctNovDecJanFebMarAprMayJunJulAugSepOctMonWedFri2025-10-26: 0 commits2025-10-27: 3 commits2025-10-28: 2 commits2025-10-29: 12 commits2025-10-30: 4 commits2025-10-31: 7 commits2025-11-01: 1 commit2025-11-02: 4 commits2025-11-03: 15 commits2025-11-04: 21 commits2025-11-05: 15 commits2025-11-06: 17 commits2025-11-07: 8 commits2025-11-08: 3 commits2025-11-09: 0 commits2025-11-10: 16 commits2025-11-11: 18 commits2025-11-12: 17 commits2025-11-13: 14 commits2025-11-14: 12 commits2025-11-15: 4 commits2025-11-16: 0 commits2025-11-17: 10 commits2025-11-18: 16 commits2025-11-19: 19 commits2025-11-20: 16 commits2025-11-21: 15 commits2025-11-22: 2 commits2025-11-23: 0 commits2025-11-24: 23 commits2025-11-25: 19 commits2025-11-26: 12 commits2025-11-27: 41 commits2025-11-28: 20 commits2025-11-29: 2 commits2025-11-30: 0 commits2025-12-01: 49 commits2025-12-02: 25 commits2025-12-03: 25 commits2025-12-04: 19 commits2025-12-05: 26 commits2025-12-06: 0 commits2025-12-07: 0 commits2025-12-08: 25 commits2025-12-09: 18 commits2025-12-10: 16 commits2025-12-11: 31 commits2025-12-12: 19 commits2025-12-13: 0 commits2025-12-14: 0 commits2025-12-15: 16 commits2025-12-16: 29 commits2025-12-17: 27 commits2025-12-18: 22 commits2025-12-19: 14 commits2025-12-20: 0 commits2025-12-21: 0 commits2025-12-22: 13 commits2025-12-23: 6 commits2025-12-24: 4 commits2025-12-25: 0 commits2025-12-26: 0 commits2025-12-27: 0 commits2025-12-28: 0 commits2025-12-29: 0 commits2025-12-30: 0 commits2025-12-31: 0 commits2026-01-01: 0 commits2026-01-02: 0 commits2026-01-03: 0 commits2026-01-04: 1 commit2026-01-05: 19 commits2026-01-06: 19 commits2026-01-07: 8 commits2026-01-08: 41 commits2026-01-09: 22 commits2026-01-10: 2 commits2026-01-11: 0 commits2026-01-12: 22 commits2026-01-13: 21 commits2026-01-14: 17 commits2026-01-15: 8 commits2026-01-16: 17 commits2026-01-17: 0 commits2026-01-18: 0 commits2026-01-19: 4 commits2026-01-20: 10 commits2026-01-21: 10 commits2026-01-22: 22 commits2026-01-23: 15 commits2026-01-24: 8 commits2026-01-25: 0 commits2026-01-26: 21 commits2026-01-27: 20 commits2026-01-28: 25 commits2026-01-29: 22 commits2026-01-30: 25 commits2026-01-31: 6 commits2026-02-01: 0 commits2026-02-02: 30 commits2026-02-03: 25 commits2026-02-04: 24 commits2026-02-05: 16 commits2026-02-06: 23 commits2026-02-07: 2 commits2026-02-08: 0 commits2026-02-09: 29 commits2026-02-10: 31 commits2026-02-11: 16 commits2026-02-12: 14 commits2026-02-13: 13 commits2026-02-14: 0 commits2026-02-15: 0 commits2026-02-16: 28 commits2026-02-17: 17 commits2026-02-18: 8 commits2026-02-19: 10 commits2026-02-20: 15 commits2026-02-21: 3 commits2026-02-22: 0 commits2026-02-23: 22 commits2026-02-24: 22 commits2026-02-25: 10 commits2026-02-26: 10 commits2026-02-27: 22 commits2026-02-28: 1 commit2026-03-01: 0 commits2026-03-02: 16 commits2026-03-03: 14 commits2026-03-04: 24 commits2026-03-05: 20 commits2026-03-06: 11 commits2026-03-07: 0 commits2026-03-08: 1 commit2026-03-09: 35 commits2026-03-10: 14 commits2026-03-11: 24 commits2026-03-12: 18 commits2026-03-13: 20 commits2026-03-14: 4 commits2026-03-15: 1 commit2026-03-16: 30 commits2026-03-17: 12 commits2026-03-18: 24 commits2026-03-19: 18 commits2026-03-20: 24 commits2026-03-21: 5 commits2026-03-22: 3 commits2026-03-23: 13 commits2026-03-24: 19 commits2026-03-25: 12 commits2026-03-26: 22 commits2026-03-27: 24 commits2026-03-28: 1 commit2026-03-29: 0 commits2026-03-30: 15 commits2026-03-31: 19 commits2026-04-01: 8 commits2026-04-02: 29 commits2026-04-03: 10 commits2026-04-04: 4 commits2026-04-05: 2 commits2026-04-06: 4 commits2026-04-07: 4 commits2026-04-08: 7 commits2026-04-09: 24 commits2026-04-10: 27 commits2026-04-11: 0 commits2026-04-12: 0 commits2026-04-13: 28 commits2026-04-14: 12 commits2026-04-15: 19 commits2026-04-16: 9 commits2026-04-17: 9 commits2026-04-18: 0 commits2026-04-19: 0 commits2026-04-20: 21 commits2026-04-21: 12 commits2026-04-22: 37 commits2026-04-23: 20 commits2026-04-24: 13 commits2026-04-25: 0 commits2026-04-26: 0 commits2026-04-27: 22 commits2026-04-28: 18 commits2026-04-29: 12 commits2026-04-30: 8 commits2026-05-01: 4 commits2026-05-02: 2 commits2026-05-03: 1 commit2026-05-04: 9 commits2026-05-05: 18 commits2026-05-06: 8 commits2026-05-07: 13 commits2026-05-08: 14 commits2026-05-09: 0 commits2026-05-10: 2 commits2026-05-11: 15 commits2026-05-12: 19 commits2026-05-13: 18 commits2026-05-14: 17 commits2026-05-15: 7 commits2026-05-16: 1 commit2026-05-17: 1 commit2026-05-18: 18 commits2026-05-19: 21 commits2026-05-20: 18 commits2026-05-21: 2 commits2026-05-22: 0 commits2026-05-23: 0 commits2026-05-24: 0 commits2026-05-25: 14 commits2026-05-26: 12 commits2026-05-27: 15 commits2026-05-28: 21 commits2026-05-29: 14 commits2026-05-30: 1 commit2026-05-31: 0 commits2026-06-01: 13 commits2026-06-02: 24 commits2026-06-03: 16 commits2026-06-04: 16 commits2026-06-05: 19 commits2026-06-06: 2 commits2026-06-07: 0 commits2026-06-08: 20 commits2026-06-09: 11 commits2026-06-10: 9 commits2026-06-11: 19 commits2026-06-12: 20 commits2026-06-13: 1 commit2026-06-14: 0 commits2026-06-15: 16 commits2026-06-16: 16 commits2026-06-17: 17 commits2026-06-18: 8 commits2026-06-19: 23 commits2026-06-20: 2 commits2026-06-21: 1 commit2026-06-22: 13 commits2026-06-23: 16 commits2026-06-24: 22 commits2026-06-25: 14 commits2026-06-26: 17 commits2026-06-27: 3 commits2026-06-28: 2 commits2026-06-29: 18 commits2026-06-30: 7 commits2026-07-01: 11 commits2026-07-02: 8 commits2026-07-03: 19 commits2026-07-04: 0 commits2026-07-05: 0 commits2026-07-06: 10 commits2026-07-07: 23 commits2026-07-08: 18 commits2026-07-09: 27 commits2026-07-10: 16 commits2026-07-11: 2 commits2026-07-12: 0 commits2026-07-13: 11 commits2026-07-14: 9 commits2026-07-15: 15 commits2026-07-16: 18 commits2026-07-17: 16 commits2026-07-18: 0 commits2026-07-19: 0 commits2026-07-20: 11 commits2026-07-21: 14 commits2026-07-22: 21 commits2026-07-23: 22 commits2026-07-24: 13 commits2026-07-25: 4 commits2026-07-26: 0 commits2026-07-27: 16 commits2026-07-28: 15 commits2026-07-29: 22 commits2026-07-30: 16 commits2026-07-31: 24 commits2026-08-01: 2 commits2026-08-02: 0 commits2026-08-03: 12 commits2026-08-04: 24 commits2026-08-05: 17 commits2026-08-06: 11 commits2026-08-07: 6 commits2026-08-08: 4 commits2026-08-09: 1 commit2026-08-10: 22 commits2026-08-11: 8 commits2026-08-12: 4 commits2026-08-13: 4 commits2026-08-14: 19 commits2026-08-15: 5 commits2026-08-16: 3 commits2026-08-17: 17 commits2026-08-18: 29 commits2026-08-19: 15 commits2026-08-20: 14 commits2026-08-21: 21 commits2026-08-22: 0 commits2026-08-23: 1 commit2026-08-24: 11 commits2026-08-25: 21 commits2026-08-26: 28 commits2026-08-27: 20 commits2026-08-28: 16 commits2026-08-29: 1 commit2026-08-30: 0 commits2026-08-31: 13 commits2026-09-01: 23 commits2026-09-02: 20 commits2026-09-03: 16 commits2026-09-04: 18 commits2026-09-05: 2 commits2026-09-06: 0 commits2026-09-07: 22 commits2026-09-08: 19 commits2026-09-09: 15 commits2026-09-10: 20 commits2026-09-11: 15 commits2026-09-12: 6 commits2026-09-13: 1 commit2026-09-14: 22 commits2026-09-15: 19 commits2026-09-16: 16 commits2026-09-17: 32 commits2026-09-18: 21 commits2026-09-19: 0 commits2026-09-20: 0 commits2026-09-21: 28 commits2026-09-22: 18 commits2026-09-23: 24 commits2026-09-24: 16 commits2026-09-25: 18 commits2026-09-26: 1 commit2026-09-27: 1 commit2026-09-28: 6 commits2026-09-29: 11 commits2026-09-30: 9 commits2026-10-01: 13 commits2026-10-02: 14 commits2026-10-03: 1 commit2026-10-04: 0 commits2026-10-05: 20 commits2026-10-06: 36 commits2026-10-07: 8 commits2026-10-08: 19 commits2026-10-09: 20 commits2026-10-10: 0 commits2026-10-11: 2 commits2026-10-12: 18 commits2026-10-13: 25 commits2026-10-14: 28 commits2026-10-15: 33 commits2026-10-16: 23 commits2026-10-17: 1 commit2026-10-18: 2 commits2026-10-19: 28 commits2026-10-20: 41 commits2026-10-21: 30 commits2026-10-22: 37 commits2026-10-23: 15 commits2026-10-24: 0 commits
4,563 commits in the last yearLessMore

Signals and awards

derived from tracked data
  • Landmark project

    168,155 stars

  • Battle-tested

    7 years of history

  • Very active

    4,563 commits in 52 weeks

  • Community-driven

    ~4,200 contributors

  • Well documented

    High community health score

  • Permissive license

    Apache-2.0

  • Continuous integration

    Automated checks passing

  • Repeat trending

    9 trending appearances

What transformers does

Transformers provides thousands of pretrained models to perform tasks on different modalities such as text, vision, and audio. It offers a unified API that allows researchers and engineers to easily download, train, and deploy state-of-the-art models like BERT, GPT, and ViT. The library abstracts away the complex boilerplate required for distributed training and model inference across PyTorch, TensorFlow, and JAX. It deeply integrates with the Hugging Face Hub, facilitating seamless model sharing and version control for the machine learning community. This significantly reduces the compute costs and engineering time required to implement cutting-edge AI features in production.

Machine learning engineers, AI researchers, and software developers who need to implement state-of-the-art AI models. It requires a solid understanding of machine learning concepts and familiarity with Python deep learning frameworks.

  • Unified API framework: Provides a consistent, simple interface to load and utilize thousands of different transformer architectures.
  • Multi-framework compatibility: Supports seamless interoperability and model conversion between PyTorch, TensorFlow, and JAX.
  • Pretrained model hub: Integrates directly with the Hugging Face Hub to instantly download state-of-the-art weights for NLP, vision, and audio.
  • Optimized training pipelines: Includes built-in classes like the Trainer API to drastically simplify distributed training and fine-tuning loops.
  • Extensive modality support: Handles complex multi-modal tasks including text classification, image segmentation, and automatic speech recognition.

Where teams use it

Natural Language Processing

Deploy state-of-the-art text classification, summarization, and translation models directly into production applications with minimal code.

Model Fine-Tuning

Fine-tune massive pre-trained language models on proprietary, domain-specific datasets using optimized training pipelines.

Computer Vision Integration

Implement cutting-edge Vision Transformers for image classification or object detection without writing custom PyTorch architectures.

Cross-Framework Migration

Train a complex transformer model in PyTorch and easily export the weights for deployment in a highly optimized TensorFlow environment.

Getting started: pip install transformers

README

main branch

Hugging Face Transformers Library

Checkpoints on Hub Build GitHub Documentation GitHub release Contributor Covenant DOI

State-of-the-art pretrained models for inference and training

Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.

It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...), and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.

We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.

There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.

Explore the Hub today to find a model and use Transformers to help you get started right away.

Installation

Transformers works with Python 3.11+, and PyTorch 2.6+.

Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.

# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate

Install Transformers in your virtual environment.

# pip
pip install "transformers[torch]"

# uv
uv pip install "transformers[torch]"

Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.

git clone https://github.com/huggingface/transformers.git
cd transformers

# pip
pip install '.[torch]'

# uv
uv pip install '.[torch]'

Quickstart

Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.

Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.

from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]

To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.

Tip

You can also chat with a model directly from the command line, as long as transformers serve is running.

transformers chat Qwen/Qwen2.5-0.5B-Instruct
import torch
from transformers import pipeline

chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]

pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])

Expand the examples below to see how Pipeline works for different modalities and tasks.

Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
Image classification
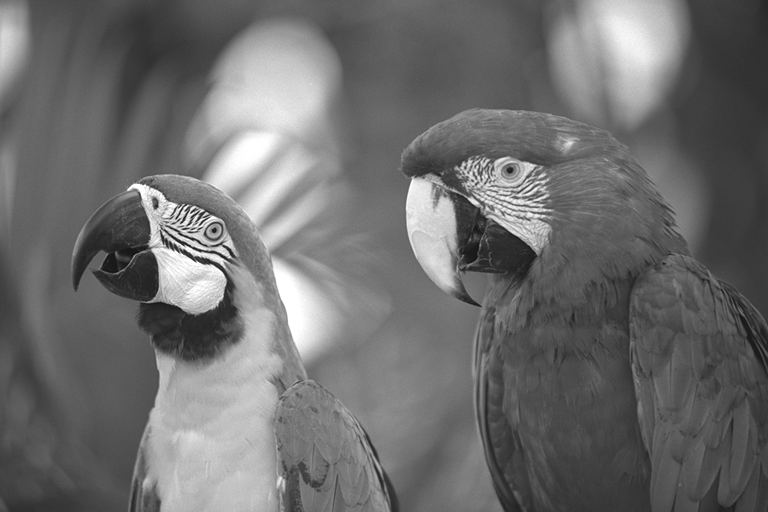
from transformers import pipeline

pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
Visual question answering
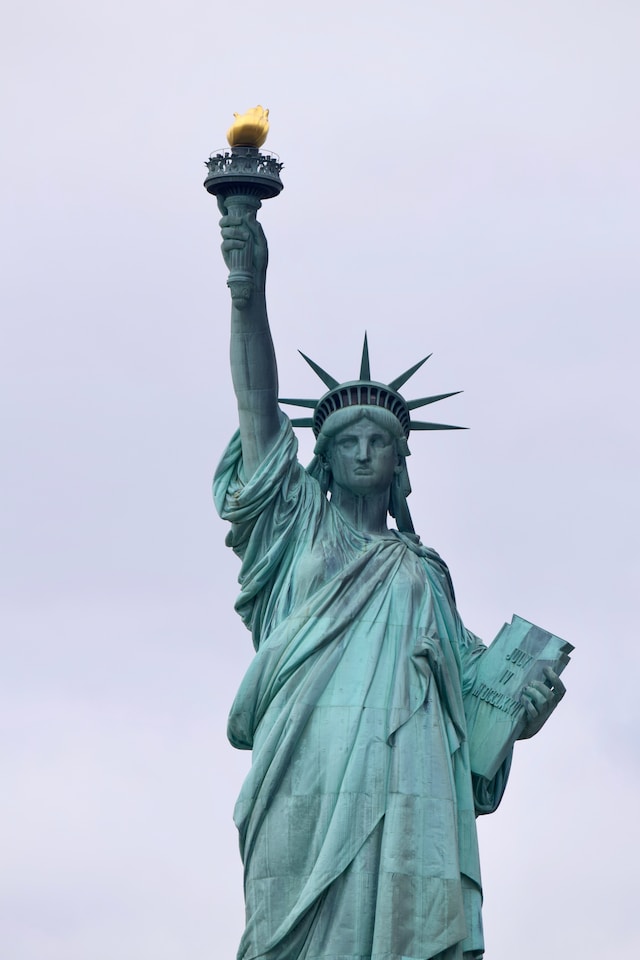
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]

Why should I use Transformers?

  1. Easy-to-use state-of-the-art models:

    • High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
    • Low barrier to entry for researchers, engineers, and developers.
    • Few user-facing abstractions with just three classes to learn.
    • A unified API for using all our pretrained models.
  2. Lower compute costs, smaller carbon footprint:

    • Share trained models instead of training from scratch.
    • Reduce compute time and production costs.
    • Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
  3. Choose the right framework for every part of a model's lifetime:

    • Train state-of-the-art models in 3 lines of code.
    • Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
    • Pick the right framework for training, evaluation, and production.
  4. Easily customize a model or an example to your needs:

    • We provide examples for each architecture to reproduce the results published by its original authors.
    • Model internals are exposed as consistently as possible.
    • Model files can be used independently of the library for quick experiments.
Hugging Face Enterprise Hub

When shouldn't I use Transformers?

  • This library is not a modular toolbox of building blocks for neural nets. The code in the model files is not refactored with additional abstractions on purpose, so that researchers can quickly iterate on each of the models without diving into additional abstractions/files.
  • The training API is optimized to work with PyTorch models provided by Transformers. For generic machine learning loops, you should use another library like Accelerate.

100 projects using Transformers

Transformers is more than a toolkit to use pretrained models, it's a community of projects built around it and the Hugging Face Hub. We want Transformers to enable developers, researchers, students, professors, engineers, and anyone else to build their dream projects.

In order to celebrate Transformers 100,000 stars, we wanted to put the spotlight on the community with the awesome-transformers page which lists 100 incredible projects built with Transformers.

If you own or use a project that you believe should be part of the list, please open a PR to add it!

Example models

You can test most of our models directly on their Hub model pages.

Expand each modality below to see a few example models for various use cases.

Audio
Computer vision
Multimodal
NLP
  • Masked word completion with ModernBERT
  • Named entity recognition with Gemma
  • Question answering with Mixtral
  • Summarization with BART
  • Translation with T5
  • Text generation with Llama
  • Text classification with Qwen

Citation

We now have a paper you can cite for the 🤗 Transformers library:

@inproceedings{wolf-etal-2020-transformers,
    title = "Transformers: State-of-the-Art Natural Language Processing",
    author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2020.emnlp-demos.6/",
    pages = "38--45"
}
View on GitHub

Recent activity

commits and pull requests

Releases and announcements

277 total
  1. Patch release v5.20.2v5.20.2Oct 19, 2026

    # Patch release: v5.20.2 This patch notably solves an issue where some inputs could loose their original type inside `prepare_inputs_for_generation` in `generate`, leading to problems with multimodal models. It also fixes some other issues listed on the below commits. It contains the following commits: - Fix inputs dict casting in generate (#49731) by @Cyrilvallez - Fix zero expert gradients in bfloat16 with expert parallelism and ep_size < fsdp_size (#49688) by @qgallouedec - Declare the input modalities of the VLMs that report text only (#49677) by @qgallouedec - Avoid a host-to-device copy in eager_mask (#49684) by @hmellor

  2. Release v5.20.1v5.20.1Oct 16, 2026

    # Release v5.20.1 Special surprise including the new model Beam from Reflection AI :partying_face: <img width="2912" height="1440" alt="Gemini_Generated_Image_ox4hjlox4hjlox4h" src="https://github.com/user-attachments/assets/bfc7ff16-4340-490c-925c-b1512e4ceb32" /> Beam is a token-efficient, frontier-scale model focused on coding and agentic use cases. It is built for teams that want to run a powerful model on their own hardware, infrastructure, or cloud, and customize it to their specific needs. **Links:** [Documentation](https://huggingface.co/docs/transformers/main/en/model_doc/beam) * Fix small bug in auto mappings (#49664) by @yonigozlan in [#49664](https://github.com/huggingface/transformers/pull/49664) ## Some real patch fixes We broke loading models on older torch versions :cry: should be fixed now. But here is the full list of fixes - Fix HunYuan-VL image assignment during batched generation (#49557) by @Arnav66692 - Fix DeepGEMM Mega MoE under expert parallelism(#49428) by @IlyasMoutawwakil - Fix from_pretrained on torch 2.7: require torch>=2.8 for distributed checkpointing (#49652) by @naveecode - Make DtensorShardOperation work on torch 2.6

  3. Release v5.20.0v5.20.0Oct 15, 2026

    # Release v5.20.0 ## New Model additions ### Muse Spark Open <img width="2400" height="1296" alt="image" src="https://github.com/user-attachments/assets/bf34ea27-0edf-4ded-ba6f-905b04096126" /> Muse Spark Open is a multimodal mixture-of-experts model from Meta that takes text, images, audio, and video as input and generates text. It has 816B total parameters (42B active per token) and a context window of up to 1,048,576 tokens shared across modalities. It is trained for agentic coding tasks such as multi-file editing, debugging, and tool use. Checkpoints are available in BF16 and NVFP4 formats. **Links:** [Documentation](https://huggingface.co/docs/transformers/main/en/model_doc/muse_spark) | [Blog Post](http://hf.co/blog/meta-muse-spark-open) * Add Muse Spark Open (#49644) by @guarin in [#49644](https://github.com/huggingface/transformers/pull/49644) ### Ling 3.0 Ling 3.0 Flash is a hybrid Mixture-of-Experts language model from InclusionAI. Its decoder groups five Kimi Delta Attention (KDA) layers with one Multi-head Latent Attention (MLA) layer. The MLA blocks use interleaved rotary embeddings and a head-wise output gate, and the feed-forward blocks comb

  4. Release v5.19.0v5.19.0Oct 6, 2026

    # Release v5.19.0 ## New Model additions ### EmbeddingGemma2 <img width="2716" height="2308" alt="image" src="https://github.com/user-attachments/assets/84734e74-163d-4d12-b166-ffcf6749d563" /> EmbeddingGemma 2 is a multimodal embedding model from Google built on the Gemma 4 architecture. It encodes text, images, audio, and video, individually or combined in one input, into a shared 768-dimensional vector space for cross-modal retrieval, semantic similarity, clustering, and classification. It uses Matryoshka Representation Learning, so embeddings can be truncated to 512, 256, or 128 dimensions. It also offers configurable visual and video token budgets, and unused vision or audio towers can be disabled at load time to save memory. **Links:** [Documentation](https://huggingface.co/docs/transformers/main/en/model_doc/embedding_gemma2) * Smthn smthn (#49364) by @vasqu in [#49364](https://github.com/huggingface/transformers/pull/49364) ## Breaking changes All MoE models whose routers compute logits now return them when `output_router_logits=True`, following the Qwen3-MoE pattern (a `router_logits` recorder on the base model, `MoeModelOutputWithPast` from the

  5. Release 5.18.0v5.18.0Sep 30, 2026

    ## New Model additions ### Nemotron 3 Diarization <img width="1680" height="900" alt="image" src="https://github.com/user-attachments/assets/fe735cb3-9e5b-43ad-8f60-9dec8425aec7" /> Nemotron 3 Diarization is an open-weight streaming speaker diarization model designed to determine "who spoke when" in real-world audio. It supports both streaming and offline inference, handles up to eight speakers, and orders speaker outputs by each speaker's first arrival in the input audio. The model uses the Arrival-Order Speaker Cache (AOSC) [1](https://huggingface.co/papers/2507.18446) and FIFO queue introduced for Streaming Sortformer [1](https://huggingface.co/papers/2507.18446), [2](https://huggingface.co/papers/2409.06656). A single checkpoint supports configurable latency profiles, from an 80 ms input buffer to a 30.4 s offline-style buffer, and configurable output frame resolution in multiples of 10 ms. With chunked inference, the maximum audio duration is not limited. **Links:** [Documentation](https://huggingface.co/docs/transformers/main/en/model_doc/nemotron3_diarization) * Add Nemotron3Diarization (#49056) by @eustlb in [#49056](https://github.com/huggingface/transfor

Commits per week

last 52 weeks
1530Week of 2025-10-26: 29 commitsWeek of 2025-11-02: 83 commitsWeek of 2025-11-09: 81 commitsWeek of 2025-11-16: 78 commitsWeek of 2025-11-23: 117 commitsWeek of 2025-11-30: 144 commitsWeek of 2025-12-07: 109 commitsWeek of 2025-12-14: 108 commitsWeek of 2025-12-21: 23 commitsWeek of 2025-12-28: 0 commitsWeek of 2026-01-04: 112 commitsWeek of 2026-01-11: 85 commitsWeek of 2026-01-18: 69 commitsWeek of 2026-01-25: 119 commitsWeek of 2026-02-01: 120 commitsWeek of 2026-02-08: 103 commitsWeek of 2026-02-15: 81 commitsWeek of 2026-02-22: 87 commitsWeek of 2026-03-01: 85 commitsWeek of 2026-03-08: 116 commitsWeek of 2026-03-15: 114 commitsWeek of 2026-03-22: 94 commitsWeek of 2026-03-29: 85 commitsWeek of 2026-04-05: 68 commitsWeek of 2026-04-12: 77 commitsWeek of 2026-04-19: 103 commitsWeek of 2026-04-26: 66 commitsWeek of 2026-05-03: 63 commitsWeek of 2026-05-10: 79 commitsWeek of 2026-05-17: 60 commitsWeek of 2026-05-24: 77 commitsWeek of 2026-05-31: 90 commitsWeek of 2026-06-07: 80 commitsWeek of 2026-06-14: 82 commitsWeek of 2026-06-21: 86 commitsWeek of 2026-06-28: 65 commitsWeek of 2026-07-05: 96 commitsWeek of 2026-07-12: 69 commitsWeek of 2026-07-19: 85 commitsWeek of 2026-07-26: 95 commitsWeek of 2026-08-02: 74 commitsWeek of 2026-08-09: 63 commitsWeek of 2026-08-16: 99 commitsWeek of 2026-08-23: 98 commitsWeek of 2026-08-30: 92 commitsWeek of 2026-09-06: 97 commitsWeek of 2026-09-13: 111 commitsWeek of 2026-09-20: 105 commitsWeek of 2026-09-27: 55 commitsWeek of 2026-10-04: 103 commitsWeek of 2026-10-11: 130 commitsWeek of 2026-10-18: 153 commitsOct 26, 2025Oct 18, 2026
4.6K commits in the last 52 weeks.

When work happens

weekday and hour
SunMonTueWedThuFriSat036912151821Sun 0:00 — 3 commitsSun 1:00 — 2 commitsSun 2:00 — 3 commitsSun 3:00 — 3 commitsSun 4:00 — 5 commitsSun 5:00 — 0 commitsSun 6:00 — 3 commitsSun 7:00 — 2 commitsSun 8:00 — 2 commitsSun 9:00 — 7 commitsSun 10:00 — 10 commitsSun 11:00 — 8 commitsSun 12:00 — 9 commitsSun 13:00 — 12 commitsSun 14:00 — 4 commitsSun 15:00 — 13 commitsSun 16:00 — 15 commitsSun 17:00 — 16 commitsSun 18:00 — 15 commitsSun 19:00 — 13 commitsSun 20:00 — 11 commitsSun 21:00 — 8 commitsSun 22:00 — 11 commitsSun 23:00 — 10 commitsMon 0:00 — 22 commitsMon 1:00 — 22 commitsMon 2:00 — 28 commitsMon 3:00 — 34 commitsMon 4:00 — 39 commitsMon 5:00 — 44 commitsMon 6:00 — 56 commitsMon 7:00 — 70 commitsMon 8:00 — 136 commitsMon 9:00 — 179 commitsMon 10:00 — 272 commitsMon 11:00 — 273 commitsMon 12:00 — 234 commitsMon 13:00 — 262 commitsMon 14:00 — 276 commitsMon 15:00 — 319 commitsMon 16:00 — 347 commitsMon 17:00 — 306 commitsMon 18:00 — 281 commitsMon 19:00 — 232 commitsMon 20:00 — 167 commitsMon 21:00 — 172 commitsMon 22:00 — 155 commitsMon 23:00 — 99 commitsTue 0:00 — 93 commitsTue 1:00 — 73 commitsTue 2:00 — 62 commitsTue 3:00 — 54 commitsTue 4:00 — 42 commitsTue 5:00 — 48 commitsTue 6:00 — 70 commitsTue 7:00 — 76 commitsTue 8:00 — 128 commitsTue 9:00 — 222 commitsTue 10:00 — 277 commitsTue 11:00 — 287 commitsTue 12:00 — 228 commitsTue 13:00 — 272 commitsTue 14:00 — 297 commitsTue 15:00 — 309 commitsTue 16:00 — 303 commitsTue 17:00 — 323 commitsTue 18:00 — 290 commitsTue 19:00 — 188 commitsTue 20:00 — 137 commitsTue 21:00 — 128 commitsTue 22:00 — 140 commitsTue 23:00 — 90 commitsWed 0:00 — 91 commitsWed 1:00 — 75 commitsWed 2:00 — 51 commitsWed 3:00 — 66 commitsWed 4:00 — 64 commitsWed 5:00 — 45 commitsWed 6:00 — 55 commitsWed 7:00 — 88 commitsWed 8:00 — 124 commitsWed 9:00 — 244 commitsWed 10:00 — 244 commitsWed 11:00 — 280 commitsWed 12:00 — 219 commitsWed 13:00 — 199 commitsWed 14:00 — 321 commitsWed 15:00 — 294 commitsWed 16:00 — 313 commitsWed 17:00 — 315 commitsWed 18:00 — 267 commitsWed 19:00 — 184 commitsWed 20:00 — 162 commitsWed 21:00 — 130 commitsWed 22:00 — 115 commitsWed 23:00 — 97 commitsThu 0:00 — 102 commitsThu 1:00 — 78 commitsThu 2:00 — 60 commitsThu 3:00 — 51 commitsThu 4:00 — 48 commitsThu 5:00 — 45 commitsThu 6:00 — 55 commitsThu 7:00 — 69 commitsThu 8:00 — 103 commitsThu 9:00 — 215 commitsThu 10:00 — 249 commitsThu 11:00 — 293 commitsThu 12:00 — 248 commitsThu 13:00 — 224 commitsThu 14:00 — 310 commitsThu 15:00 — 333 commitsThu 16:00 — 281 commitsThu 17:00 — 310 commitsThu 18:00 — 220 commitsThu 19:00 — 165 commitsThu 20:00 — 122 commitsThu 21:00 — 113 commitsThu 22:00 — 112 commitsThu 23:00 — 78 commitsFri 0:00 — 63 commitsFri 1:00 — 52 commitsFri 2:00 — 49 commitsFri 3:00 — 46 commitsFri 4:00 — 38 commitsFri 5:00 — 38 commitsFri 6:00 — 34 commitsFri 7:00 — 47 commitsFri 8:00 — 92 commitsFri 9:00 — 183 commitsFri 10:00 — 217 commitsFri 11:00 — 249 commitsFri 12:00 — 238 commitsFri 13:00 — 212 commitsFri 14:00 — 243 commitsFri 15:00 — 290 commitsFri 16:00 — 273 commitsFri 17:00 — 250 commitsFri 18:00 — 219 commitsFri 19:00 — 144 commitsFri 20:00 — 121 commitsFri 21:00 — 103 commitsFri 22:00 — 93 commitsFri 23:00 — 81 commitsSat 0:00 — 42 commitsSat 1:00 — 25 commitsSat 2:00 — 31 commitsSat 3:00 — 18 commitsSat 4:00 — 12 commitsSat 5:00 — 9 commitsSat 6:00 — 8 commitsSat 7:00 — 9 commitsSat 8:00 — 12 commitsSat 9:00 — 17 commitsSat 10:00 — 11 commitsSat 11:00 — 17 commitsSat 12:00 — 10 commitsSat 13:00 — 8 commitsSat 14:00 — 11 commitsSat 15:00 — 10 commitsSat 16:00 — 18 commitsSat 17:00 — 10 commitsSat 18:00 — 10 commitsSat 19:00 — 17 commitsSat 20:00 — 11 commitsSat 21:00 — 13 commitsSat 22:00 — 17 commitsSat 23:00 — 5 commits
Commit volume by weekday and hour (UTC). Larger dots mean more commits.
DateListRankStars gained
Oct 11, 2026daily#8+94
Oct 10, 2026daily#8+94
Sep 20, 2026weekly#17+1,297
Sep 19, 2026weekly#17+1,297
Sep 15, 2026daily#13+152
Sep 14, 2026daily#13+152
Sep 13, 2026daily#15+102
Aug 13, 2026daily#10+80
Aug 12, 2026daily#10+80
  • public-apis/public-apis

    A collective list of free APIs

    492.1K stars · Python

  • morluto/rea

    Reverse engineer anything with agents, from app behavior down to native binaries.

    384.3K stars · TypeScript

  • donnemartin/system-design-primer

    Learn how to design large-scale systems. Prep for the system design interview. Includes Anki flashcards.

    375.6K stars · Python

  • affaan-m/ECC

    The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.

    288.8K stars · JavaScript

  • practical-tutorials/project-based-learning

    Curated list of project-based tutorials

    288K stars · Python

  • NousResearch/hermes-agent

    The agent that grows with you

    257K stars · Python